Henrik Ingo, MySQL Community Architect at Oracle, highlighted MyVector in “MySQL Development as it Happens, Part 2 – Vector Indexes” on the official Oracle MySQL Blog.
The post surveys the community effort to bring native vector indexes to InnoDB, with ScaNN, IVF, HNSW and Vamana all on the table and Google, AWS, Intel and Percona involved. It points out that MyVector has been running in production since March, ahead of all of them. It also gives MyVector its own section, covering HNSW and IVF indexes, exact and approximate kNN search, multiple distance functions and binlog-driven index maintenance. Henrik uses it as an example of extending MySQL through plugins.
A plugin started the fire, the M-ecosystem picked it up, the hyperscalers went native, and now the benchmark wars have begun.
Not long ago, if you asked about vector search in MySQL, you got a polite smile and a link to pgvector. Even after MySQL 9 added a VECTOR column type, the obvious next questions had no answer. Where is the index? Where is the distance function? For a while the honest answer was “use something else.”
This week the MySQL Contributor Summit (Nov 4–5, online) opened its technical program with vector search. The first discussion block, AI & Cloud, had four vector and AI proposals back to back from Oracle, Google, Percona and Intel. It was the clearest sign yet of how far vector search in MySQL has come.
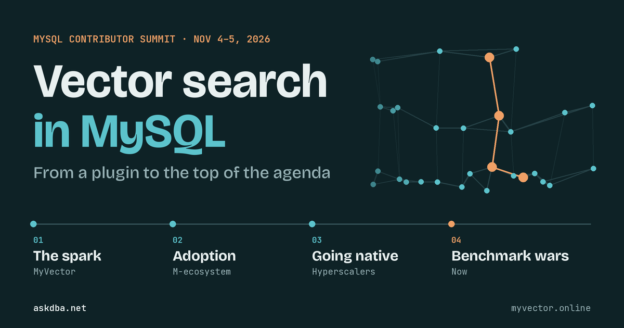
Looking back, vector search in MySQL has moved through four phases:
The spark: MyVector
Adoption: the M-ecosystem picks up the idea
Going native: the hyperscalers arrive
The benchmark wars: where we are now
Phase 1: The spark, MyVector
We didn’t want to wait for a server release, so I co-founded MyVector, which I now own. It gives MySQL HNSW indexing, distance functions and approximate nearest neighbor search, all open source.
MyVector started as a plugin on MySQL 8.0. It has since moved to MySQL’s component architecture, which is far more robust on recent MySQL releases, and it now supports MySQL Community Edition 8.4, 9.7 and 26.10.
We took it to FOSDEM and SCALE, and the conversation changed from “MySQL can’t do this” to “wait, MySQL can do this?” You can try it yourself at demo.myvector.online.
Phase 2: Adoption, the M-ecosystem picks it up
Once MyVector showed that vector search fits naturally inside a MySQL-compatible engine, the idea spread across the M-ecosystem. MariaDB, TiDB, VillageSQL and Percona all started adopting the idea in their own products and distributions.
Each took its own path, but they all headed the same way: embeddings belong next to the data, inside the database people already run.
Phase 3: Going native, the hyperscalers arrive
The third phase is native implementations, with contributions now coming from the hyperscalers and the biggest names in the ecosystem. You could see it at the summit, where the four AI & Cloud talks came from the upstream owner, a hyperscaler, a fork vendor and a chip maker:
Session
From
GitHub
Evolving MySQL VECTOR Support: Native Indexing and Similarity Search Mayank Prasad, Kuba Lopuszanski
Evgeniy Patlan set the ground rules with vector-bench, an open harness that runs each engine in its own pinned container on the same cores with the same data. Every measurement is a pair of throughput and recall, and recall is a setting, not a property of the engine.
I ran MyVector on MySQL against MariaDB Vector on 50,000 vectors. MariaDB’s first run came in at only 29 QPS. Instead of publishing that, I traced it to the 16 MB default HNSW cache, which could not hold the 27 MB index, and reran it.
lefred answered: two QPS figures at different recall are not apples to apples. He estimated MariaDB at matched recall, showed that a bigger cache cut index build from about 583 to 92 seconds, and argued the 16 MB default deserves a rethink. Fair points, made in good faith.
MariaDB est. ≈ 1,196 QPS @ recall 0.82 · build 583 s → 92 s
Adam Levin, working with Percona, released vector-dev-bench, a laptop-scale companion that answers in minutes. It sweeps ef_search and measures what writers cost readers.
Every round raised the bar. The community converged on pairing throughput with recall, exposing defaults and testing writes alongside reads. MyVector is being added to vector-bench as an engine, so anyone will be able to rerun the numbers. Results for MyVector and other engines are published side by side at bench.myvector.online. That is how an open-source ecosystem decides something matters.
The spark is now a fire.
Why this matters
We have seen this pattern before. JSON in MySQL went through the same steps: store it as text, then a native type, then functions, then indexes, and finally the default choice.
Vectors are moving through those steps much faster, because a plugin proved it was possible, the ecosystem adopted it, the hyperscalers are building it in, and the benchmarks keep everyone honest.
For teams running MySQL in production, the question is moving away from “which separate vector database?” and toward “can my embeddings live next to my transactional data, in the database my team already knows how to run?”
Join the conversation
The Contributor Summit is open and online. Proposals are filed as issues in the mysql/mysql-community GitHub repo, and the hallway track continues in the MySQL Community Slack in #contributor-summit-hallway-track. If you work on vector search in MySQL, bring your ideas, your pull requests and your benchmarks to the next one.
What’s next
Native indexing and similarity search proposals moving through upstream design review
Standard DISTANCE() functions replacing vendor-specific workarounds
MyVector continuing as a way to run vector search on MySQL Community Edition today, with open, reproducible benchmarks
We’re not done. Thanks to Heather VanCura and the MySQL Community team for running an open, design-review-style summit.
MyVector has been featured as the MySQL Ecosystem Project Spotlight of the Week in the MySQL group on LinkedIn. Thank you to Lilly Berry and the MySQL community team for the shout-out!
This week, we’re spotlighting MyVector, an open source plugin that brings vector storage and similarity search capabilities to MySQL. Semantic search and recommendation features open up exciting possibilities for MySQL applications, giving developers a way to explore those possibilities using familiar SQL tools. Keeping vector search alongside application data may eliminate the need for a separate ETL pipeline for certain use cases.
With HNSW indexing and a SQL interface, MyVector offers an interesting starting point for developers building applications around embeddings. It’s also a great example of the MySQL community extending what developers can do with the database.
Lilly Berry, Communications @ Oracle, in the MySQL group on LinkedIn
If you’re exploring semantic search or recommendations with MySQL, take a look at the documentation, try the examples, and share your feedback.