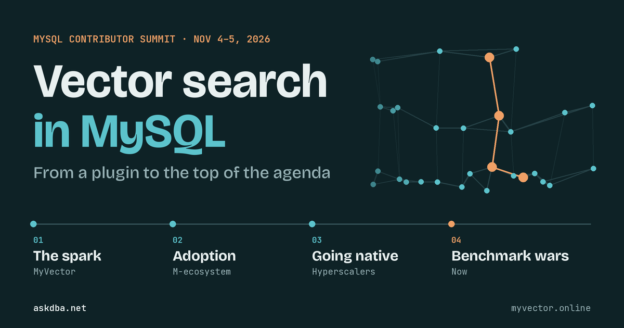
MySQL Contributor Summit, Nov 4–5, 2026: vector search in MySQL in four phases, from the MyVector spark to the benchmark wars

Vector search in MySQL: from a plugin to the top of the Contributor Summit agenda

A plugin started the fire, the M-ecosystem picked it up, the hyperscalers went native, and now the benchmark wars have begun.

Not long ago, if you asked about vector search in MySQL, you got a polite smile and a link to pgvector. Even after MySQL 9 added a VECTOR column type, the obvious next questions had no answer. Where is the index? Where is the distance function? For a while the honest answer was “use something else.”

This week the MySQL Contributor Summit (Nov 4–5, online) opened its technical program with vector search. The first discussion block, AI & Cloud, had four vector and AI proposals back to back from Oracle, Google, Percona and Intel. It was the clearest sign yet of how far vector search in MySQL has come.

Looking back, vector search in MySQL has moved through four phases:

  1. The spark: MyVector
  2. Adoption: the M-ecosystem picks up the idea
  3. Going native: the hyperscalers arrive
  4. The benchmark wars: where we are now

Phase 1: The spark, MyVector

We didn’t want to wait for a server release, so I co-founded MyVector, which I now own. It gives MySQL HNSW indexing, distance functions and approximate nearest neighbor search, all open source.

MyVector started as a plugin on MySQL 8.0. It has since moved to MySQL’s component architecture, which is far more robust on recent MySQL releases, and it now supports MySQL Community Edition 8.4, 9.7 and 26.10.

We took it to FOSDEM and SCALE, and the conversation changed from “MySQL can’t do this” to “wait, MySQL can do this?” You can try it yourself at demo.myvector.online.

Phase 2: Adoption, the M-ecosystem picks it up

Once MyVector showed that vector search fits naturally inside a MySQL-compatible engine, the idea spread across the M-ecosystem. MariaDB, TiDB, VillageSQL and Percona all started adopting the idea in their own products and distributions.

Each took its own path, but they all headed the same way: embeddings belong next to the data, inside the database people already run.

Phase 3: Going native, the hyperscalers arrive

The third phase is native implementations, with contributions now coming from the hyperscalers and the biggest names in the ecosystem. You could see it at the summit, where the four AI & Cloud talks came from the upstream owner, a hyperscaler, a fork vendor and a chip maker:

SessionFromGitHub
Evolving MySQL VECTOR Support: Native Indexing and Similarity Search
Mayank Prasad, Kuba Lopuszanski
OracleIssue #3
Invoking AI models from MySQL
Julia Offerman
GoogleIssue #158
DISTANCE() Functions for the VECTOR Data Type
Catalin Besleaga
PerconaPR #860
Bringing SVS’s Graph-Based Vector Search to MySQL
Kelly L. McKeighan
IntelIssue #116
AI & Cloud discussion block, MySQL Contributor Summit Fall 2026, followed by a design review with all attendees

All four brought proposals, bug reports and pull requests for the same feature.

Phase 4: The benchmark wars

With several implementations in play, the next step was inevitable: people started measuring in public and answering each other’s numbers.

Percona, Aug 27: Benchmarking vector indexes

Evgeniy Patlan set the ground rules with vector-bench, an open harness that runs each engine in its own pinned container on the same cores with the same data. Every measurement is a pair of throughput and recall, and recall is a setting, not a property of the engine.

ef_search 10 → 800 · recall 0.959 → 0.999 · 3,678 → 409 QPS

askdba, Oct 14: How fast is vector search inside MySQL?

I ran MyVector on MySQL against MariaDB Vector on 50,000 vectors. MariaDB’s first run came in at only 29 QPS. Instead of publishing that, I traced it to the 16 MB default HNSW cache, which could not hold the 27 MB index, and reran it.

MyVector ≈ 548 QPS @ recall 0.82 · MariaDB ≈ 257 QPS @ recall 0.95

lefred (MariaDB), Oct 16: Vector Search in MySQL vs MariaDB: Look Beyond QPS

lefred answered: two QPS figures at different recall are not apples to apples. He estimated MariaDB at matched recall, showed that a bigger cache cut index build from about 583 to 92 seconds, and argued the 16 MB default deserves a rethink. Fair points, made in good faith.

MariaDB est. ≈ 1,196 QPS @ recall 0.82 · build 583 s → 92 s

VillageSQL, Oct 22: Benchmarking vector indexes in MySQL with vector-dev-bench

Adam Levin, working with Percona, released vector-dev-bench, a laptop-scale companion that answers in minutes. It sweeps ef_search and measures what writers cost readers.

20k × 32-dim · recall 0.787 → 0.988 · 8,829 → 2,044 QPS · reads −40% with writers

Every round raised the bar. The community converged on pairing throughput with recall, exposing defaults and testing writes alongside reads. MyVector is being added to vector-bench as an engine, so anyone will be able to rerun the numbers. Results for MyVector and other engines are published side by side at bench.myvector.online. That is how an open-source ecosystem decides something matters.

The spark is now a fire.

Why this matters

We have seen this pattern before. JSON in MySQL went through the same steps: store it as text, then a native type, then functions, then indexes, and finally the default choice.

Vectors are moving through those steps much faster, because a plugin proved it was possible, the ecosystem adopted it, the hyperscalers are building it in, and the benchmarks keep everyone honest.

For teams running MySQL in production, the question is moving away from “which separate vector database?” and toward “can my embeddings live next to my transactional data, in the database my team already knows how to run?”

Join the conversation

The Contributor Summit is open and online. Proposals are filed as issues in the mysql/mysql-community GitHub repo, and the hallway track continues in the MySQL Community Slack in #contributor-summit-hallway-track. If you work on vector search in MySQL, bring your ideas, your pull requests and your benchmarks to the next one.

What’s next

  • Native indexing and similarity search proposals moving through upstream design review
  • Standard DISTANCE() functions replacing vendor-specific workarounds
  • MyVector continuing as a way to run vector search on MySQL Community Edition today, with open, reproducible benchmarks

We’re not done. Thanks to Heather VanCura and the MySQL Community team for running an open, design-review-style summit.
Links

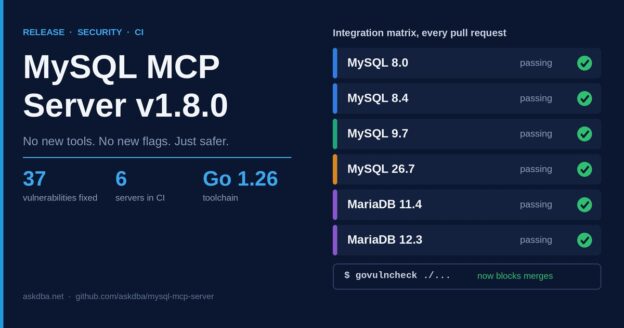
MySQL MCP Server v1.8.0: 37 vulnerabilities fixed, integration tests passing on MySQL 8.0, 8.4, 9.7, 26.7 and MariaDB 11.4, 12.3

MySQL MCP Server v1.8.0 is out

On paper it’s a boring release. No new tools, no new flags, nothing to reconfigure. In practice it’s one I’m glad I didn’t skip: it closes 37 known vulnerabilities that the server could actually reach, and I found them more or less by accident.


It started as a compatibility check

I had MySQL 8.4, 9.7 and 26.7 running on my test box, plus MariaDB 12.3. So I pointed the MCP server’s test suite at all of them. Mostly to tick a box before moving on to something more fun.

The code was fine. Every version passed.


MySQL 26.7 and MariaDB 12.3 join the matrix

Every pull request now runs the full integration suite against six servers:

  • MySQL 8.0, 8.4, 9.7 and 26.7
  • MariaDB 11.4 and 12.3

26.7 is the first Innovation release under Oracle’s new calendar versioning. If you follow MyVector, you know I’ve been chasing it there too.

MySQL 9.0 is out of CI. It was a short-lived Innovation release, and 9.7 covers that line now.

MySQL 8.0 is staying. Yes, it reached end of life in April. No, I’m not dropping it. Plenty of you are still on 8.0 and haven’t moved to 8.4 yet, and I’d rather keep testing it than pretend otherwise.

One more thing turned up along the way. The Sakila tests weren’t running in CI at all: the sample database was never loaded, so they skipped quietly. They run now, on every version.


Green CI, 37 vulnerabilities

CI was not fine. The vulnerability scan and the linter had been failing quietly for a while. Both were set to informational, so nothing ever turned red.

Once the scan ran again, it found 37 vulnerabilities in code the server actually calls. Most were in the Go 1.24 standard library, the rest in the SSH and MCP SDK dependencies.

v1.8.0 fixes all of them:

  • Go 1.24 → 1.26
  • golang.org/x/crypto v0.43.0 → v0.58.0
  • MCP Go SDK v1.2.0 → v1.8.0

If you use the SSH tunnel: that library jumped 15 minor versions, so I tested it through a bastion before tagging. It still connects, and it still refuses a server whose host key doesn’t match known_hosts.

And since the release, govulncheck blocks merges and releases, so this can’t quietly happen again.


Release candidates stay out of Homebrew

This one’s a bit embarrassing. When I cut v1.7.1, all four release candidates went straight to the Homebrew tap. If you ran brew upgrade that week, you got an RC. Sorry about that.

RCs now only show up on the GitHub releases page. brew upgrade only ever gives you a final release.

v1.8.0 went out the new way. rc.1 first, smoke-tested against real 8.4, 9.7, 26.7 and MariaDB 12.3 servers, then the final tag. Homebrew users never saw the RC.


Things I learned the hard way

Two, mostly.

First, don’t write [skip ci] in a commit message. Not even when you’re describing a different commit that had it. GitHub doesn’t read for context. My PR sat there with no CI run at all while I wondered what was going on. With a required check on main now, that PR would have stayed stuck until I reworded the commit.

Second, the AI code reviewers earned their keep this time. CodeRabbit spotted a startup race in the CI health checks. Codex pointed out that scanning on Linux alone misses Windows-only code. And Copilot noticed that one of my test fixes would have broken the release workflow on the very first tag. I would have found that one at release time, which is the worst time to find anything.


Upgrading

Breaking change: building from source now needs Go 1.26 or later. Homebrew, Docker and the release binaries aren’t affected, and there’s nothing to reconfigure.

Homebrew:

brew update && brew upgrade mysql-mcp-server

Docker:

docker pull ghcr.io/askdba/mysql-mcp-server:1.8.0

Or grab a binary from the v1.8.0 release. Here’s what my Mac said after brew upgrade:

$ mysql-mcp-server --version
mysql-mcp-server 1.8.0
  Build time: 2026-10-17T09:14:37Z
  Git commit: f946f1d37654b5d8958d45a027a3e68133f01d1a

The full list is in the CHANGELOG. Questions, bugs and ideas are welcome on GitHub.

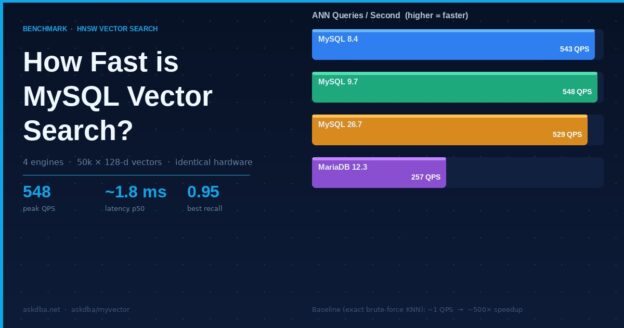
Bar chart showing MySQL vector search benchmark: 548 QPS for MySQL 9.7, 257 QPS for MariaDB 12.3

How fast is vector search inside MySQL?

Benchmarks · HNSW vector search

MyVector adds approximate nearest-neighbor search to stock MySQL — no separate vector database. We put it on identical hardware across three MySQL versions, added MariaDB’s native vector type as a reference, and measured build time, throughput, latency, and recall on the same data.

askdba/myvector · live dashboard at bench.myvector.online

548
peak ANN queries/sec (MySQL 9.7), ~1.8 ms median
0.95
best recall@10 (MariaDB 12.3) once tuned
4×
engines, one 50k×128 workload, identical 4 vCPU / 24 GB slices

Why benchmark this at all

Vector search usually means standing up a dedicated database next to your primary store, then keeping the two in sync. MyVector takes the other path: it lives inside MySQL as UDFs and stored procedures, builds an HNSW index over a column of vectors, and answers nearest-neighbor queries in SQL. The obvious question is whether that convenience costs you speed or accuracy.

To answer it honestly we needed a level field. Every engine runs in its own container on one Ampere A1 host, each pinned to the same 4 vCPU / 24 GB slice, loading the same 50,000 synthetic 128-dimensional vectors (seeded, so every engine indexes identical data), and builds an HNSW index with the same parameters (M=16, ef_construction=200, L2 distance). Three of the four are MySQL running MyVector — versions 8.4, 9.7 and 26.7. The fourth is MariaDB 12.3, which ships its own native VECTOR type, included as a cross-engine reference point.

What each number means

Five measurements, each isolating one thing:

  • Index build — wall-clock seconds to build the HNSW graph over all 50k rows.
  • Insert throughput — rows/sec written into a live, indexed table.
  • ANN QPS & latency — approximate nearest-neighbor queries per second through the index, and their median response time.
  • Recall@10 — of the true 10 nearest neighbors (found by exact brute-force search), how many the approximate search actually returns, averaged over held-out queries that were never inserted. 1.0 is perfect; 0.82 means it finds ~8 of the real 10.
  • ef_search sweep — the accuracy/throughput trade-off: searching more of the graph raises recall but lowers QPS.

Results

The headline is throughput. On identical A1 hardware, all three MySQL versions clear ~530–550 approximate queries per second at ~1.8 ms median — roughly 500× faster than the exact brute-force scan (~1 QPS) they fall back to without an index. 8.4, 9.7 and 26.7 land within a few percent of each other, so moving to a newer MySQL costs nothing here.

Approximate nearest-neighbor throughput at the default operating point (ef_search=200). Higher is better. All four engines on identical Ampere A1 hardware.
Recall@10 at the same operating point. The three MyVector builds land at 0.82; MariaDB 12.3 reaches 0.948 — it trades some speed for accuracy in how it walks the graph.

The real picture: accuracy vs throughput

A single QPS number hides the trade-off. The ef_search knob lets each query decide how hard to look: low values are fast but miss neighbors, high values are accurate but slow. Plotting recall against QPS across that sweep is the honest comparison — up and to the right is better.

Each point is one ef_search setting (10 → 200). MariaDB’s curve sits higher on recall at a given speed; the MySQL/MyVector curves reach higher raw QPS. All share the same synthetic ground truth.
EngineBuild (s)Insert QPSANN QPSANN p50 (ms)Recall@10

Exact brute-force KNN measured ~1 QPS (~700 ms) on every engine — the baseline the index is beating.

The MariaDB surprise

The first MariaDB run looked grim: 29 ANN QPS, a 583-second build, recall aside. Taken at face value it was 15× behind MySQL. That gap was too large to be a real engine difference, so we dug in.

The cause was one default. MariaDB caches its HNSW graph in memory up to mhnsw_max_cache_size, which ships at 16 MB — but the index for this dataset is ~27 MB. The graph didn’t fit, so every search and the whole online build re-read nodes from disk. MyVector sidesteps this by loading its entire index into memory, so the default pitted a disk-bound MariaDB against an in-memory MyVector.

Sizing the cache above the index changed everything:

MariaDB 12.3, same data and hardware, cache at its 16 MB default vs sized above the index. ANN throughput rose ~9×; build dropped from 583 s to 92 s; recall improved from 0.85 to 0.95. (Search alone, measured in isolation, was ~15× faster.)

The lesson, not the leaderboard

Properly configured, MariaDB’s native vector search is competitive with MyVector on speed and ahead on recall. The takeaway isn’t a winner — it’s that a single cache default can make one engine look an order of magnitude slower than it is. Benchmarks are only as fair as their configuration, which is why the setup here is in the open.

Takeaways

  • Native MySQL vector search is fast. ~530–550 QPS at single-digit-millisecond latency on 4 modest cores, ~500× over brute force — without a second database to run.
  • Newer MySQL isn’t slower. 8.4, 9.7 and 26.7 land within a few percent of each other; there’s no regression moving forward.
  • MariaDB 12.3 holds its own once its HNSW cache fits the index — higher recall, comparable throughput.
  • Configuration is part of the result. The most interesting finding wasn’t a speed number; it was a default that quietly handicapped an engine 15×.

Every number here is reproducible. The live, interactive dashboard is at bench.myvector.online, and the benchmark harness and raw results live in github.com/askdba/myvector under scripts/bench-dashboard. Workload: 50,000 × 128-d vectors, L2 distance, HNSW M=16 / ef_construction=200, held-out queries for recall, each engine pinned to 4 vCPU / 24 GB on Ampere.

Movie Finder: semantic search over 1M films, inside MySQL

Type “a heist that goes wrong in a snowy town” and get back real films, with posters, in a few milliseconds. The vector search behind it runs inside MySQL, with no separate vector database.

Movie Finder is the new demo app that ships with MyVector. It searches up to 1,035,695 TMDB movies by meaning, not keywords. One docker compose up gives you the whole thing: MySQL 9.7 with the MyVector component, a loader, and a small web app.

Try it live: https://demo.myvector.online/

We built it to answer the questions people ask us most. Does vector search in MySQL hold up at a million rows? Can I mix it with ordinary WHERE filters? What happens when I insert a new row? The demo shows the answers on the page, with the SQL that ran under every result.

Live: What you can do on the page

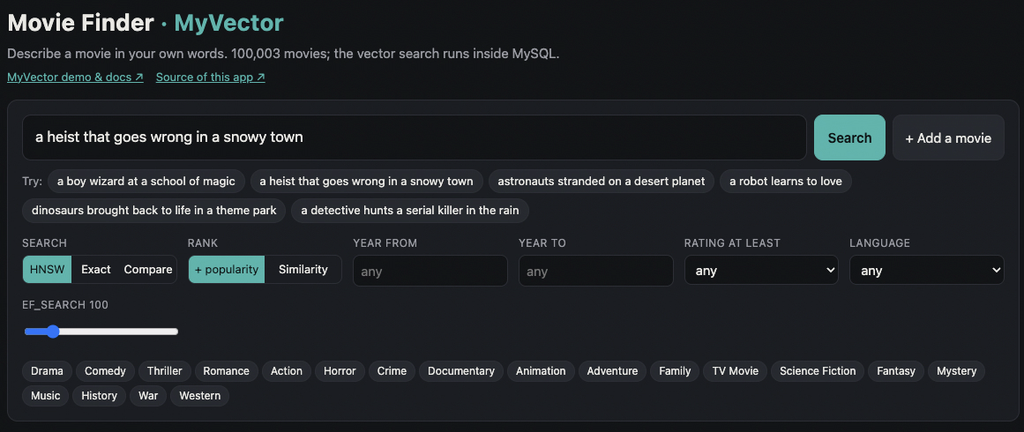
Every feature on the page maps to a MyVector capability, and every result panel shows its SQL.

  • Describe a movie in your own words and get the nearest films. Ask for “a boy wizard at a school of magic” and Harry Potter comes back first.
  • Filter by genre, year, rating and language. These are plain SQL predicates combined with the vector search, and the page tells you which filtered-search path ran and why.
  • Rank by similarity alone, or with a small boost for films many people have rated, so the famous match beats an obscure one at almost the same distance. Both are ordinary ORDER BY expressions.
  • More like this: a film’s stored vector becomes the next query, in pure SQL.
  • HNSW vs exact: run both side by side and compare speed and recall.
  • Add a movie: a plain INSERT, searchable within about a second, with no index rebuild. (Not on live demo)
  • Under the hood: live index details from myvector_index_status, a bar showing where each query’s time went, and a speed-vs-recall chart that sweeps ef_search from 10 to 640 against an exact scan.

How it works

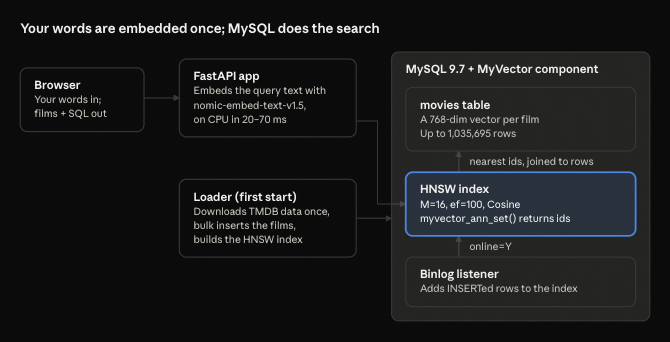
The app embeds only your query text; every movie’s vector already sits in MySQL, so a search is one SQL round trip. The movie vectors come with the dataset, made by nomic-embed-text-v1.5 from each film’s title, tagline, and overview. The app uses the same model locally on the CPU, so there is no API key, and nothing leaves your machine.

New rows need no rebuild. Adding a movie is a plain INSERT; MyVector’s binlog listener picks it up and adds it to the HNSW index, usually within a second.

The SQL

The whole index is declared in a column comment. This is the movies table’s vector column:

embedding VARBINARY(3080) COMMENT
  'MYVECTOR COLUMN type=HNSW,dim=768,size=...,M=16,ef=100,dist=Cosine,online=Y,idcol=id,threads=N'

The loader inserts the rows, then builds the HNSW index with one call:

CALL mysql.myvector_index_build('movies.movies.embedding', 'id');

A search turns the query vector into a nearest-first list of ids with myvector_ann_set(), then joins back to the table. JSON_TABLE keeps the order:

SELECT m.title, myvector_distance(m.embedding, @q, 'Cosine') AS distance
FROM (SELECT myvector_ann_set('movies.movies.embedding', 'id', @q,
                              'nn=10,ef_search=100') AS js) src,
     JSON_TABLE(src.js, '$[*]' COLUMNS (rank_no FOR ORDINALITY, id INT PATH '$')) nn
JOIN movies.movies m ON m.id = nn.id
ORDER BY nn.rank_no;

“More like this” needs no embedding at all. It reads a film’s stored vector into the query variable:

SELECT embedding INTO @q FROM movies.movies WHERE id = @movie_id;

Filters pick one of two paths. The app counts each filter on its own index and takes the smallest count as an upper bound:

  • 50,000 matches or fewer: it passes the matching keys as the fifth argument of myvector_ann_set, so HNSW searches only among them.
  • More than that: it calls MYVECTOR_ANN_FILTERED, which takes the nearest candidates and keeps those that pass the filter.

Run it yourself

To run your own copy, from a clone of the repository:

cd examples/movie-finder
MOVIES=100k docker compose up      # then open http://localhost:8080

The first start downloads the TMDB data, about 7 GB, once. MOVIES picks how many films to load, most-voted first: 10k, 100k (the default) or full. Measured on a 16-core Arm (Neoverse-N1) Linux host with MySQL 9.7.2:

Step10k100kfull (1,035,695)
Insert7 s41 s407 s
Build the HNSW index (16 threads)29 s33 s545 s
HNSW search3–5 ms4–7 ms5–20 ms
Exact search (scans every row)30 ms280 ms3 s warm
Recall@10, HNSW vs exact100%100%100%

At a million movies, HNSW answers in 5–20 ms where a full scan takes 3 seconds, with the same top 10. Recall is for the unfiltered test query; a broad genre filter (Drama) at full size gave 80% at ef_search 100, and the page lets you raise ef_search to trade time for recall. For the full profile, give Docker about 12 GB of memory and set MYSQL_BUFFER_POOL=6G.

Running it on a remote server? The page and MySQL listen on localhost only. Forward the port instead of opening it: ssh -N -L 8080:127.0.0.1:8080 <server>.

Version note: the demo uses features newer than the v1.26.9 images: filtered search, MYVECTOR_ANN_FILTERED, per-query ef_search, and online updates that survive a restart. Until the next release ships, the README shows how to build a local image from main.

Data: the movie metadata and posters come from TMDB via a Hugging Face mirror. Your machine downloads it; it is not in the repository or any image. This is a non-commercial demo, not endorsed by TMDB.

Try it and tell us

Try the live demo first. To run your own, start with MOVIES=10k for a quick first look, then go to full to watch a million rows answer in milliseconds. The demo guide has screenshots and the other demos; the Movie Finder README has the full details.

If a query surprises you, or you want a feature the page doesn’t show yet, open an issue on GitHub. A star helps other MySQL users find the project.

MyVector v1.26.9: Keeping Up With MySQL Innovation

MySQL 26.7 Innovation Support Lands


September 22, 2026 · ⁠GitHub Release

MySQL just changed the rules.

With MySQL 26.7, Oracle has moved to a new calendar-based versioning model for Innovation releases. For MyVector, that means one thing:

We need to keep up.

MyVector v1.26.9 adds MySQL 26.7 Innovation support, but the more interesting story is what happened beneath the surface.

This release puts the Component architecture introduced in v1.26.5 through a much more serious test.

From architecture to reliability

When we introduced the MySQL Component architecture in v1.26.5, the goal was straightforward: build MyVector in the direction MySQL itself is taking.

Now we are testing what happens when things don’t go perfectly.

v1.26.9 adds proper Component lifecycle testing, including installation, uninstallation, failed removal, and deinitialization rollback.

Because installing something is easy.

Installing, removing, failing, restarting, and recovering correctly is the real test.

HNSW gets harder to kill

There is also some important HNSW work in this release.

A number of failure paths around HNSW index creation and persistence have been fixed, including a case where an index build could crash mysqld.

That obviously isn’t acceptable.

We also fixed configuration handling so type=hnsw is correctly honored, and persistence failures are now surfaced instead of disappearing silently.

If MyVector cannot save an index, you should know about it.

Does it survive a restart?

This became an explicit test in v1.26.9.

It is one thing to create an index and run a vector search.

It is another thing to restart MySQL and have that index come back.

The new lifecycle tests verify that persisted indexes are actually reloaded from disk.

That is an important distinction as MyVector moves from an interesting MySQL extension toward something people can consider for real workloads.

The release process got better too

v1.26.9 also expands the testing and release pipeline around:

  • MySQL 26.7 compatibility
  • Component lifecycle
  • HNSW
  • Persistent indexes
  • Online updates
  • Stress testing
  • Stanford dataset smoke tests
  • Benchmark failure detection
  • Docker builds

What’s next?

The original MyVector idea hasn’t changed:

Why move your data to another database just because your application needs vector search?

The answer is becoming more interesting as MySQL evolves.

With MyVector, the goal is to bring:

SQL + transactional data + vector search + full-text search + AI workloads

into the same database environment.

MySQL 26.7 brings a new Innovation release.

MyVector 1.26.9 makes sure we’re ready to follow it.

v1.26.5 was about introducing the Component architecture.

v1.26.9 is about proving it.

Get MyVector

⁠MyVector v1.26.9

⁠GitHub Repository

⁠Documentation

MyVector is open source. Feedback, issues, benchmarks, and contributions are welcome.

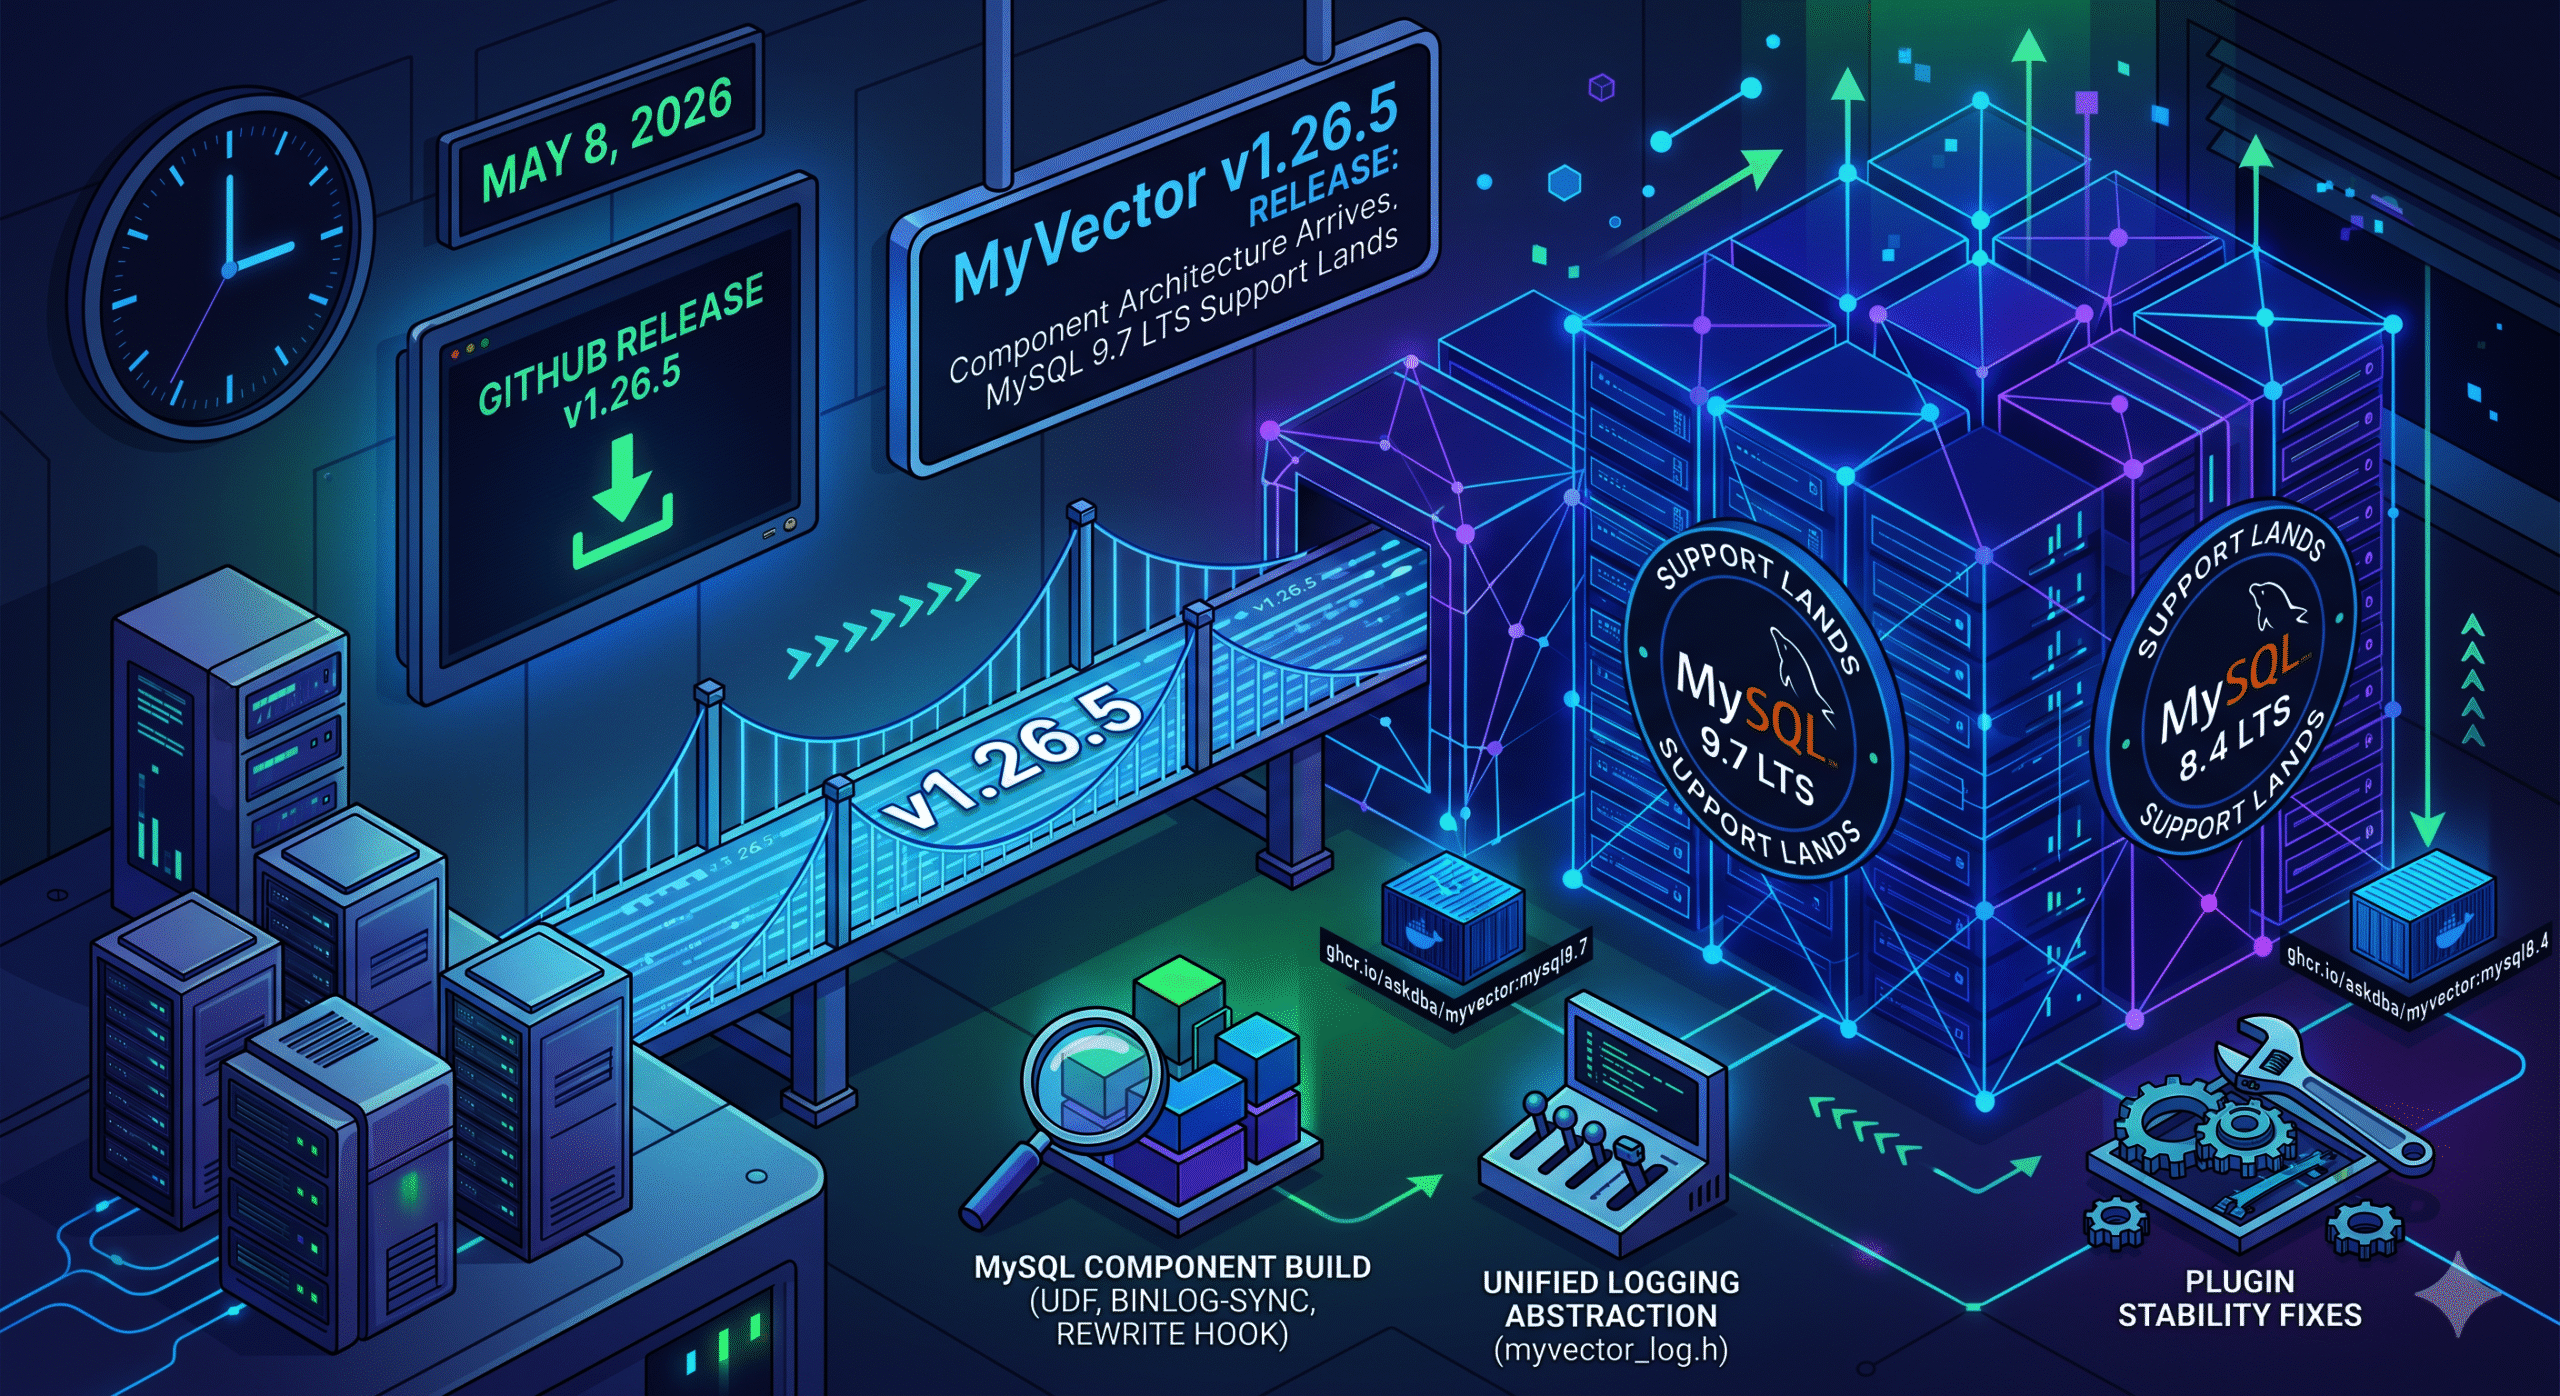
MyVector v1.26.5: Component Architecture Arrives

MySQL 9.7 LTS Support Lands Released May 8, 2026 · GitHub Release

v1.26.5 introduces a MySQL Component build for MySQL 8.4 LTS and 9.7 LTS, a unified logging abstraction, and a set of plugin stability fixes. The plugin path for MySQL 8.0, 8.4, and 9.0 is unchanged.

Why the Component architecture matters

MySQL has been deprecating the legacy plugin API in favor of the Component architecture since 8.0. Components install via INSTALL COMPONENT, integrate through typed service interfaces, and are better isolated from server internals — meaning fewer breakages across MySQL minor versions and a supported path forward as the plugin API winds down. For MyVector, this move isn’t optional in the long run: the component model is where MySQL’s extension ecosystem is heading, and building on it now means users on 8.4 LTS and 9.7 LTS get a stable, upgrade-resilient foundation rather than a deprecated one.

What’s New

MySQL Component build. MyVector can now be installed via INSTALL COMPONENT on MySQL 8.4 and 9.7. The component ships UDF registration, binlog-driven index synchronization, and a query rewrite service hook — all backed by the same core vector index engine as the plugin. A new myvector_log.h abstraction unifies logging across both build modes, replacing scattered #ifdef blocks.

MySQL 9.7 LTS. The 9.x CI, release, and Docker targets move from 9.6 to 9.7 LTS. A new Docker image tag ghcr.io/askdba/myvector:mysql9.7 is now available. If you’re on :mysql9.6, switch to :mysql9.7.

Plugin stability fixes. gmtime() and asctime() replaced with their thread-safe _r variants; concurrency fixes in plugin init/deinit; null-guard added to myvector_ann_set row function. Also: config file permission hardening, a binary_log namespace conflict fix on 8.4/9.7, and a Quick Start wget URL correction (issue #89).

How to Install

Component — pre-built binaries (Linux amd64) are attached to this release:

bash

tar -xzf myvector-component-mysql8.4.8-linux-amd64.tar.gz
cp libmyvector_component.so $(mysql_config --plugindir)/
mysql -u root -p -e "INSTALL COMPONENT 'file://libmyvector_component';"

Also available: myvector-component-mysql9.7.0-linux-amd64.tar.gz and checksums.txt. To build from source, use scripts/build-component-8.4-docker.sh or scripts/build-component-9.7-docker.sh.

Plugin — Docker or build from source. Pre-built plugin .so files are not on the release page. Use Docker (multi-arch, amd64 + arm64):

bash

docker pull ghcr.io/askdba/myvector:mysql8.4   # or :mysql8.0, :mysql9.7

Or build from source with scripts/build-release.sh (requires MySQL dev headers).

Upgrade Notes

  • No schema or index migration required.
  • Docker tag change: :mysql9.6 → :mysql9.7.
  • The component path is the forward path for MySQL 8.4+. The plugin remains supported for 8.0/8.4/9.0 through their EOL dates.
  • Windows is not supported — use Linux container images.

See docs/BUILD_MODES.md and docs/COMPONENT_MIGRATION_PLAN.md for migration guidance. Bugs and feedback welcome on GitHub Issues.

MySQL 9.7 is out and the community wins 

May 2026 · 5 min read. Alkin Tezuysal

Cross blog from Oracle https://blogs.oracle.com/mysql/mysql-9-7-is-out-and-the-community-wins

MySQL 9.7 came out on April 21 and I’ve been going through the release notes so you don’t have to. The short version: Oracle has made several previously Enterprise-only features available in the Community Edition; the Hypergraph Optimizer is now free for everyone; and if you’re still on MySQL 8.0, it has reached End-of-Life. Like right now. We’ll get to that.

Let’s go through what matters most.

First: MySQL 8.0 has reached End-of-Life

MySQL 8.0.46 shipped alongside 9.7, and it is the last 8.0 release. As of April 2026, 8.0 is officially End-of-Life. No more security patches. No more bug fixes. Oracle’s release notes now encourage users to upgrade to MySQL 8.4 LTS or 9.7.

If you’re on 8.0 in production, you’ve got two paths. MySQL 8.4 LTS is the safest, most conservative upgrade with a well-trodden migration path from 8.0. MySQL 9.7 is if you want all the new stuff, including everything in this post. Either way, the clock has run out on 8.0. It is strongly recommended to plan your upgrade soon.

Some Enterprise features available in the Community Edition

This is the headline. Oracle has moved five components from Enterprise Edition into Community Edition with this release. For self-hosted MySQL users, this is genuinely good news.

Four of them are replication components that now ship in Community Edition.

Replication Applier Metrics gives you real visibility into how your replica is processing events. Lag monitoring, throughput, the works. This was always the kind of thing you had to implement separately or access the Enterprise Edition.

Group Replication Flow Control Statistics now provides visibility into why your GR cluster is throttling. If you’ve ever stared at a slow cluster and had no idea what was happening under the hood, this one’s for you.

Group Replication Resource Manager lets you control how resources get allocated so replication stops starving your app workloads.

Group Replication Primary Election gives better observability into failover behavior during primary elections, which is exactly when you most need to know what’s going on.

And then there’s the Telemetry component, which is big if you’re running MySQL in a cloud-native setup. Metrics and traces can now flow to Prometheus, OpenTelemetry, and whatever else your observability stack includes. This was Enterprise-only until today.

The Hypergraph Optimizer is in Community Edition now

This is the one that stands out as particularly impactful.

Quick background: MySQL’s traditional query optimizer uses a left-deep tree approach to figure out join order. Works fine for simple queries, but with complex multi-table joins it can miss a lot of better execution plans. The Hypergraph Optimizer takes a completely different approach. It models the whole query as a hypergraph and uses dynamic programming to search a much bigger space of possible plans.

If you’ve got complex reporting queries or anything with a lot of joins, it’s worth turning on and seeing what happens.

To try it:

SET optimizer_switch=’hypergraph_optimizer=on’;

You can set it at session scope (great for testing), globally, persistently across restarts, or hint it on a per-query basis. Start with session scope on your actual slow queries before you go global. The optimizer is solid, but you don’t want surprises in production.

JSON Duality Views are now fully supported in Community

Previously, in Community Edition, you could define JSON Duality Views, but couldn’t do INSERTs, UPDATEs, or DELETEs through them. That was an Enterprise thing. This capability is now available in Community Edition. Full DML is now in Community.

They also added auto-increment support for duality view inserts, which means you can stop manually wiring up primary keys:

INSERT INTO orders_view

VALUES (‘{“customer_id”: 42, “product_id”: 7, “quantity”: 3}’);

The order_id gets generated automatically. Small change, but it removes a real friction point if you’ve been experimenting with duality views.

A few other things worth knowing

Password hashing got stronger.caching_sha2_password now supports PBKDF2 with SHA-512 storage format. Your existing clients don’t need to change anything since this is server-side only, but it makes stored hashes significantly harder to brute-force. Worth noting if you’re in a compliance-heavy environment like PCI-DSS or HIPAA.

Rolling upgrades just got easier. There’s a new variable called replica_allow_higher_version_source that lets a lower-version replica connect to a higher-version primary. Practically, this means you can upgrade your primary first, verify everything looks good, and then roll through your replicas at your own pace instead of taking the whole fleet down at once.

Container users, this one’s for you. MySQL now correctly reads cpuset cgroup limits to figure out how many CPUs are actually available to it. If you’d constrained MySQL to 4 CPUs in Kubernetes, it might have been sizing its thread pools against all 32 host CPUs anyway. That’s fixed.

OpenSSL got bumped to 3.5.5. Not exciting, but good hygiene.

What about Vector search?

A lot of people are asking about this, and the current status is that it is not yet generally available. Oracle is clearly building toward native vector search across the 9.x innovation releases, and you can see pieces of the foundation being put in place. But 9.7 isn’t the release where it lands as something you can use. It’s on the roadmap, it’s coming, the team is looking for feedback, and it is expected in future releases.  As some of you know, I’m especially interested in vector features as a maintainer of the MyVector project. We’ve had a couple of calls with the engineering team to collaborate on this subject. This might be an area for community contributions. Please stay tuned. 

So, should you upgrade?

Your situationWhat to do
Still on MySQL 8.0Upgrade. It’s EOL. Pick 8.4 LTS or 9.7.
On 8.4 LTS, happy where you areNothing urgent. Track 9.7 for the LTS landing.
Running Group ReplicationTry the new components.
Complex JOIN-heavy queriesBenchmark the Hypergraph Optimizer.
Running MySQL in KubernetesThe cgroup CPU fix alone might be worth it.
Excited about vector searchNot yet. Watch this space.


MySQL 9.7 is available at dev.mysql.com/downloads. If you end up benchmarking the Hypergraph Optimizer or trying the new replication components, share your results. The community learns from real-world numbers a lot more than from release notes. Drop them in the MySQL Community Forums or tag #MySQL97.

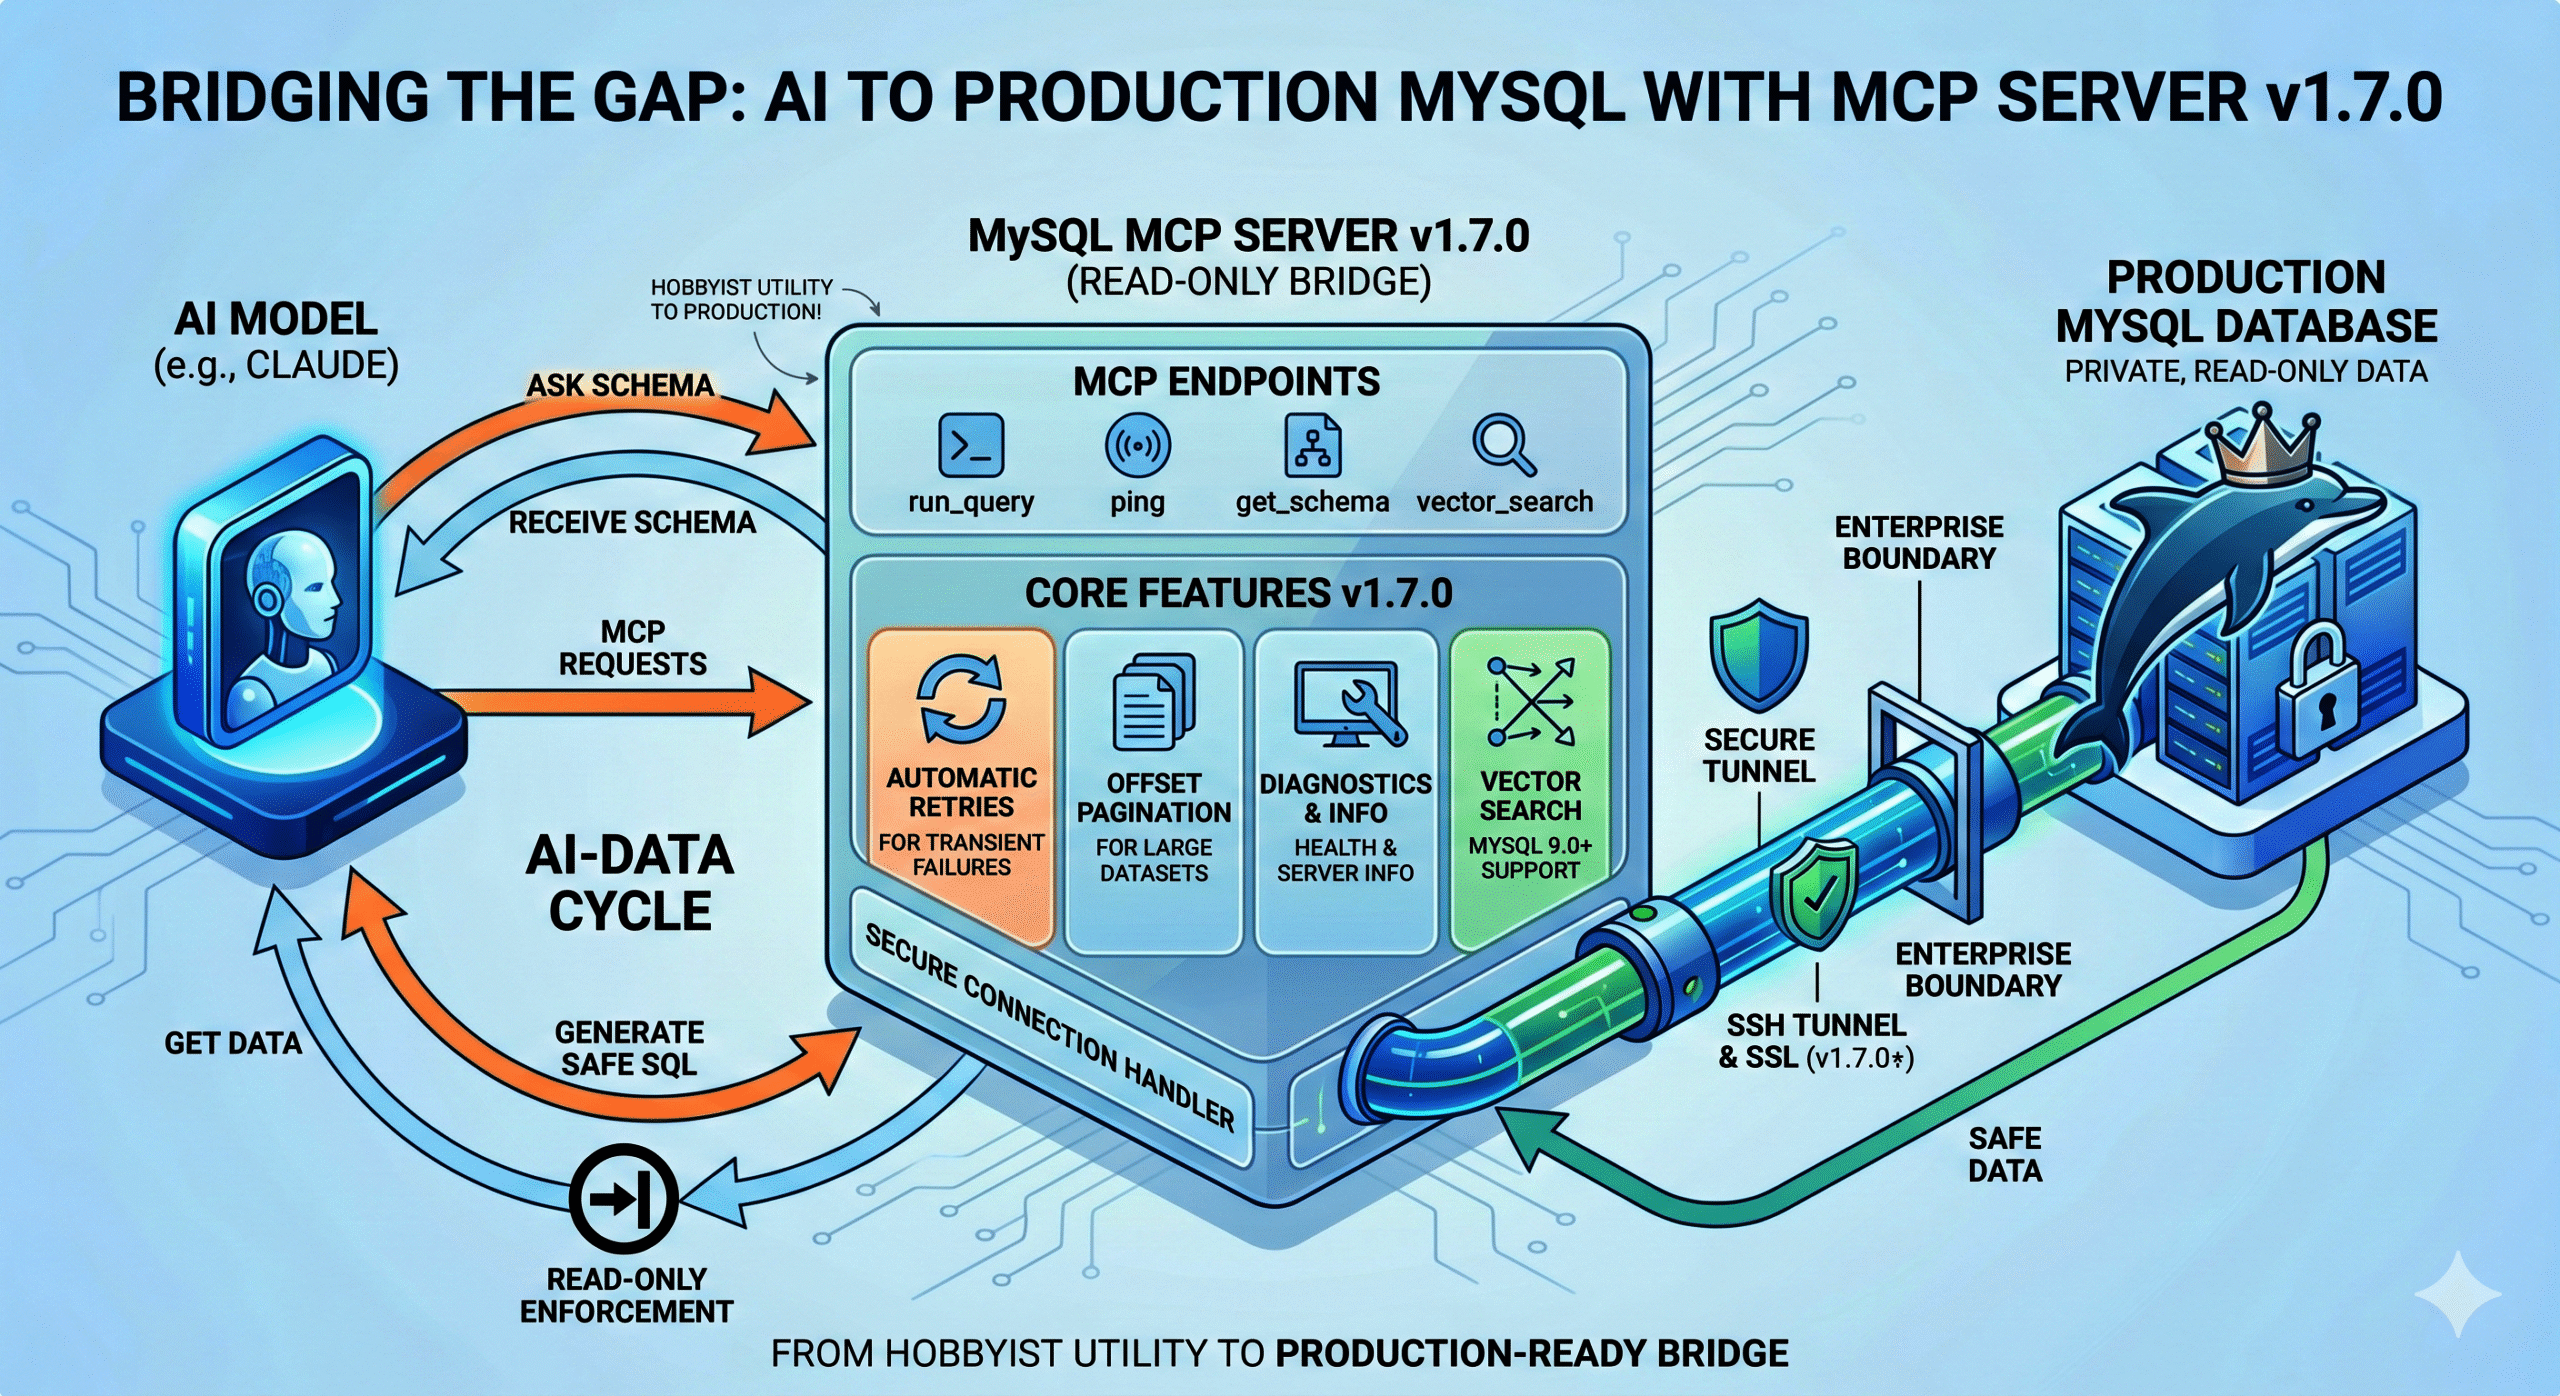
MySQL MCP Server v1.7.0 is out

April 19, 2026

It took three release candidates and more CI tweaks than I’d like to admit, but v1.7.0 is finally tagged GA. Here’s what actually changed and why it matters.


The thing I kept getting asked about: add_connection

Almost every multi-database user hits the same wall: you configure your connections at startup, and that’s it. Want to point Claude at a different instance mid-session? Restart the server. Not great.

add_connection fixes that. Enable it with MYSQL_MCP_EXTENDED=1 and MYSQL_MCP_ENABLE_ADD_CONNECTION=1, and Claude can register a new named connection on the fly — DSN validation, duplicate-name rejection, and a hard block on the root MySQL user all happen before the connection is accepted. Once it’s in, use_connection it works as usual.

It’s intentionally opt-in behind two flags. Allowing an AI client to register arbitrary database connections at runtime warrants an explicit “yes, I want this” from the operator.


Finding stuff across a big schema: search_schema and schema_diff

Two tools I personally felt the absence of every time I was debugging a large schema.

search_schema does what it sounds like — pattern-match against table and column names across all accessible databases. Before this, you’d either write the query yourself or ask Claude to guess where a column lived. Now you just ask.

schema_diff is the one I’m more excited about. Point it at two databases, and it tells you what’s structurally different. Columns that exist in staging but not prod, type mismatches, missing indexes — all surface immediately. We’ve already caught more than a few “oh, that migration never ran” moments with it.


Pagination, retries, and the unglamorous stuff

run_query now supports an offset parameter for SELECT and UNION queries, returning has_more and next_offset in the response. Big result sets no longer mean hitting row caps and wondering what you missed.

Retries got a proper implementation too. Transient errors — bad pooled connections, deadlocks, lock wait timeouts — now trigger exponential backoff instead of just failing. After a driver.ErrBadConn the pool is re-pinged, which cuts recovery time noticeably after a MySQL restart.

Neither of these is flashy, but they’re the kind of thing that makes the tool feel solid rather than fragile.


Column masking

Set MYSQL_MCP_MASK_COLUMNS=email,password,ssn and those columns are redacted in every run_query response. Nothing leaves the server. No query rewrites, no application changes. It’s a small feature that a few teams have been asking for since before v1.6.


One breaking change worth knowing about: SSH host key verification

This one could bite you on upgrade if you’re using SSH tunnels. Host key verification is now on by default. The tunnel checks ~/.ssh/known_hosts (or MYSQL_SSH_KNOWN_HOSTS, or a pinned MYSQL_SSH_HOST_KEY_FINGERPRINT) before allowing the connection.

If you were running without strict host key checking, your tunnel will fail after upgrading until you either add the host key to known_hosts or explicitly opt out with MYSQL_SSH_STRICT_HOST_KEY_CHECKING=false. The opt-out exists, but it’s a MITM risk — the default is the right behavior.


Upgrading

# Homebrew
brew update && brew upgrade mysql-mcp-server

# Docker
docker pull ghcr.io/askdba/mysql-mcp-server:latest

Full changelog: github.com/askdba/mysql-mcp-server/releases/tag/v1.7.0

Questions and issues are welcome on GitHub.

Navigating Business Challenges: Insights from Sailing

Some experiences can be simulated.

Sailing cannot, and it ever changes.

At first glance, a sailboat feels like leisure, wind, sea, and escape from reality. But the moment you take responsibility on board, that illusion disappears.

A sailboat is not an escape from life. It is a lifestyle full of responsibilities.

As we enter the sailing season, I wanted to take a few notes on how sailing aligns with the business life we live every day.

A Boat Is an Organization

A sailboat is, in essence, a fully functioning micro-organization.

  • The wind represents external market forces, unpredictable, uncontrollable, yet decisive.
  • The route is your strategy, chosen deliberately, but constantly under pressure to adapt.
  • The crew is your organization, each role critical, each mistake amplified.
  • The captain embodies leadership, not authority, but responsibility.

Unlike corporate environments, where feedback loops are often delayed or diluted, sailing delivers immediate and unambiguous consequences. A poor decision is not debated; it is felt. Instantly, no regrets, only lessons learned.

Reality Has No Buffer

At sea, there is no delay.
In most environments, reality is delayed through reports, meetings, and layers of interpretation. At sea, there is no such delay. If you are wrong, the boat tells you immediately. If communication fails, the system breaks immediately. There are no explanations, only outcomes.

If you’re wrong, the boat tells you immediately. If communication fails, the system breaks immediately.

No explanations. Just outcomes.

Leadership Is Behavior

On land, leadership can hide behind structure. At sea, it can’t. I sometimes say me, myself, and I, even though I have a crew with me.

I often just smile and don’t say anything.

There are no layers, no escalation paths, no time to reframe the narrative. Sometimes, the best and life-saving advice is to gear up with your life jacket if you haven’t already.

Only:

  • What you see and its relevance to your experience.
  • What you decide. There’s no right or wrong at sea. What you decide is what you’ll have to face.
  • What you communicate. There are a lot of assumptions; avoid them. Be clear and concise.

Teamwork Is Binary

Collaboration is not a “nice to have”; it either works or it doesn’t.

A maneuver with:

  • Slight hesitation
  • Unclear communication
  • Assumptions instead of alignment

will have consequences.

Nothing else can be more harmful than a precise decision.

Adapt or Stall

Plans don’t survive contact with reality. Wind shifts. Conditions change severely. You don’t debate it.

You adapt conditions continuously.

The Hidden Lesson

After a few hours, something shifts in people.

Less talking.

More observing.

Clearer communication.

Because reality leaves no room for ego.

Why It Matters

Sailing compresses how real systems behave:

  • Immediate feedback
  • Clear cause and effect
  • Shared exposure

It teaches what most environments dilute:

  • Decision-making
  • Communication
  • Accountability
  • Adaptation

But more than anything, it gives you something rare:

Final Thought

A sailboat is one of the few environments where there is no AI involved.

Only human, trained coordination.

That is exactly why it works.

Not as an escape, but as a mirror of how we actually operate under pressure.

Follow the adventure at @svrubato

v1.26.3

MyVector v1.26.3: Maintenance, CI, and Readiness for MySQL 9.7


In my recent series on Scoped Vector Search, we looked at the query patterns that make vector search a first-class citizen in MySQL. While the logic for those searches is now established, the infrastructure supporting them requires constant attention as the MySQL ecosystem moves toward its new release model.

Today, I’m announcing MyVector v1.26.3. This is a foundational release focused on environment compatibility and CI/CD robustness.

What’s in v1.26.3?

This release ensures that MyVector remains stable and buildable across the shifting landscape of MySQL Innovation and LTS releases.

  • MySQL 8.4 & 9.6 Compatibility: We’ve updated the component sources and build logic to align with the headers and requirements for MySQL 8.4 (LTS) and the 9.6 Innovation release.
  • Ready for 9.7: The build system has been adapted to handle the upcoming 9.7 release, ensuring that users can transition to the next Innovation branch without delay.
  • Modernized Release Workflow: We’ve bumped our GitHub Actions (softprops/action-gh-release) from v1 to v2. While invisible to the user, this ensures our release pipeline remains secure and compatible with the latest GitHub runner environments.

Think of v1.26.3 as the “maintenance and readiness” layer that ensures the high-performance HNSW search you rely on continues to compile and run perfectly on the newest versions of MySQL.

Looking Ahead: The Architecture Pivot (PR #76)

While v1.26.3 keeps us current, the real excitement is happening in the lab.

There is a fundamental architecture change currently in development under Component migration (8.4–9.6) and release workflow update.

Unlike the compatibility fixes in today’s release, PR #76 is a structural overhaul. We are re-engineering how the plugin interacts with the MySQL core. This shift is designed to move MyVector closer to a full Component Architecture, which will eventually offer better lifecycle management and even deeper integration with MySQL’s internal services.

This is a significant pivot in how MyVector is built, and it will set the stage for the next generation of vector performance and observability.

Summary

v1.26.3 is the stable, verified update you need for today’s MySQL 8.4/9.6 environments and tomorrow’s 9.7 upgrade. Meanwhile, work continues on the architectural evolution that will define the future of the project.