I’m grateful to all my professional and personal networks for this year. It has been full of tears, sweat, and blood all over my face once again. Let’s not worry about that. I want to start with a big Thank You to all of you who made this year possible.
If I look back at what stood out in 2025, just before we hit 2026.
Oracle ACE Pro
I was thrilled to be nominated to the Oracle ACE Program as an ACE Pro in April. This recognition opened doors to launch a technical blog series on vector search and AI integration with MySQL.
Project Antalya at Altinity, Inc.
We announced native Iceberg catalog and Parquet support on S3 for ClickHouse. This pushes the boundaries of what’s possible with open lakehouse analytics.
MySQL MCP Server
Introduced a lightweight, secure MySQL MCP server bridging relational databases and LLMs. Practical AI integration starts with safety and observability.
FOSDEM & MySQL’s 30th Birthday
I have one of my busiest agendas in ten years. It includes the MySQL Devroom Committee, a talk, and an O’Reilly book signing for #mysqlcookbook4e. Additionally, there are 6 talks from Altinity.
O’Reilly Recognition
After 50+ hours of flights for conferences, I came home to O’Reilly’s all-time recognition for the MySQL Cookbook. It was a moment I won’t forget.
Sailing While Working
Once again, months at sea with salt, humidity, and wind were challenging. We handled tickets, RCAs, and meetings. We even recorded a podcast on ferry maneuvering. Born to sail, forced to work, making it work anyway.
I am immensely grateful to the #MySQL, #ClickHouse, and #opensource communities. Thank you to my co-authors Sveta Smirnova and Ibrar Ahmed. I also thank my nominator, Vinicius Grippa. I appreciate the Altinity team and every conference organizer who gave me a stage this year.
Recognition is an invitation to contribute more, not a finish line. Looking forward to more open-source collaboration in 2026.
If you’re passionate about open-source databases, MySQL, ClickHouse, or AI integration, or just want to connect, reach out.
A lightweight, secure, and extensible MCP (Model Context Protocol) server for MySQL designed to bridge the gap between relational databases and large language models (LLMs).
I’m releasing a new open-source project: mysql-mcp-server, a lightweight server that connects MySQL to AI tools via the Model Context Protocol (MCP). It’s designed to make MySQL safely accessible to language models, structured, read-only, and fully auditable.
This project started out of a practical need: as LLMs become part of everyday development workflows, there’s growing interest in using them to explore database schemas, write queries, or inspect real data. But exposing production databases directly to AI tools is a risk, especially without guardrails.
mysql-mcp-server offers a simple, secure solution. It provides a minimal but powerful MCP server that speaks directly to MySQL, while enforcing safety, observability, and structure.
What it does
mysql-mcp-server allows tools that speak MC, such as Claude Desktop, to interact with MySQL in a controlled, read-only environment. It currently supports:
Listing databases, tables, and columns
Describing table schemas
Running parameterized SELECT queries with row limits
Running as either a local MCP-compatible binary or a remote REST API server
By default, it rejects any unsafe operations such as INSERT, UPDATE, or DROP. The goal is to make the server safe enough to be used locally or in shared environments without unintended side effects.
Why this matters
As more developers, analysts, and teams adopt LLMs for querying and documentation, there’s a gap between conversational interfaces and real database systems. Model Context Protocol helps bridge that gap by defining a set of safe, predictable tools that LLMs can use.
mysql-mcp-server brings that model to MySQL in a way that respects production safety while enabling exploration, inspection, and prototyping. It’s helpful in local development, devops workflows, support diagnostics, and even hybrid RAG scenarios when paired with a vector index.
Getting started
You can run it with Docker:
docker run -e MYSQL_DSN='user:pass@tcp(mysql-host:3306)/' \
  -p 7788:7788 ghcr.io/askdba/mysql-mcp-server:latest
Not knowing whether you need a mentor or not at the beginning.
People often assume that mentorship is something you outgrow. They imagine it as a ladder. It’s something you climb early in your career. Once you reach a certain level of success, you step off and stand on your own.
In reality, the opposite is true. The higher you go, the more critical mentorship becomes. I’ve learned this repeatedly throughout my career in open source, in leadership, and in life.
Success Doesn’t Eliminate Blind Spots
When you achieve success, you start to hear less honest feedback. People around you become careful with their words. Colleagues hesitate to challenge your ideas. Slowly, your perspective narrows. It happens not out of arrogance. It’s hard to see what no one reflects back at you.
That’s where a mentor makes all the difference. A good mentor isn’t impressed by your title or your achievements. They see you as the person behind the professional identity. They’ll challenge your assumptions and remind you that growth never stops, no matter how far you’ve come.
Learning Never Ends
The world around us moves too fast for anyone to claim mastery. Technologies evolve, leadership philosophies change, and the definition of success itself shifts over time.
Mentorship keeps you learning. It introduces you to new ways of thinking, new perspectives, and new generations. It forces you to stay curious, and curiosity is what keeps leaders relevant.
In my years working with global database communities, I’ve seen brilliant engineers become stagnant simply because they stopped seeking input. The best ones? They’re still asking questions, still open to being mentored.
Every Step Forward Is New Territory
No matter how experienced you are, every stage of career growth is unexplored terrain. Each new role, responsibility, or challenge introduces conditions you’ve never faced. There are new dynamics, new expectations, and sometimes, new vulnerabilities.
Mentors are the ones who’ve walked those paths already. They know where the turns are, where you stumble, and how to prepare for what’s coming next. They help you see beyond the horizon of your current comfort zone.
That foresight is the ability to anticipate the next chapter of your journey. It is one of the most valuable gifts mentorship offers. It opens your mind to possibilities you have never considered. It helps you approach the unknown with clarity rather than fear.
The Lonely Space at the Top
Leadership is often described as empowering, and it is, but it’s also lonely. You carry responsibilities that few others truly understand. You can’t always be vulnerable with your team or share the full weight of the decisions you make.
Having a mentor gives you a space to breathe. Someone who listens without judging, who helps you find balance when everything feels heavy. Sometimes, mentorship isn’t about advice at all. It’s about presence and perspective. It’s about being reminded that you’re not alone in figuring it out.
From Achievement to Legacy
There’s a point where success stops being about how much you achieve and starts being about what you enable. Mentorship helps you make that shift.
It turns experience into impact. It teaches you how to guide others. It shows you how to pass on lessons without ego. You learn how to translate hard-earned wisdom into something that outlives your career. Every time I’ve been mentored, I’ve become a better mentor myself. I think that is the real cycle of growth.
The Real Value of Mentorship
I’ve come to see mentorship not as a career stage, but as a lifelong relationship with learning. It keeps you honest. It keeps you grounded. And it ensures that success doesn’t harden into comfort.
If anything, mentorship is a mirror. It helps you stay true to your principles. It also connects you to your evolution and your humanity.
No matter how much experience I gain, I’ll always seek mentors. Because the moment I stop learning from others is the moment I stop growing.
This is why I still believe in mentorship even after a successful career. In conclusion, have I had a dedicated mentor in my career? The short answer is no, but I’ve had role models along the way. I’ve used them as my mentors and always asked them what would I do if I were them.
In Part 1, we introduced the MyVector plugin — a native extension that brings vector embeddings and HNSW-based approximate nearest neighbor (ANN) search into MySQL. We covered how MyVector supports scoped queries (e.g., WHERE user_id = X) to ensure that semantic search remains relevant, performant, and secure in real-world multi-tenant applications.
Now in Part 2, we move from concept to implementation:
How to store and index embeddings
How to design embedding workflows
How hybrid (vector + keyword) search works
How HNSW compares to brute-force search
How to tune for performance at scale
1. Schema Design for Vector Search
The first step is designing tables that support both structured and semantic data.
A typical schema looks like:
CREATE TABLE documents (
    id BIGINT PRIMARY KEY,
    user_id INT NOT NULL,
    title TEXT,
    body TEXT,
    embedding VECTOR(384),
    INDEX(embedding) VECTOR
);
Design tips:
Use VECTOR(n) to store dense embeddings (e.g., 384-dim for MiniLM).
Always combine vector queries with SQL filtering (WHERE user_id = …, category = …) to scope the search space.
Use TEXT or JSON fields for hybrid or metadata-driven filtering.
Consider separating raw text from embedding storage for cleaner pipelines.
2. Embedding Pipelines: Where and When to Embed
MyVector doesn’t generate embeddings — it stores and indexes them. You’ll need to decide how embeddings are generated and updated:
a. Offline (batch) embedding
Run scheduled jobs (e.g., nightly) to embed new rows.
Suitable for static content (documents, articles).
Can be run using Python + HuggingFace, OpenAI, etc.
# Python example
from sentence_transformers import SentenceTransformer
model = SentenceTransformer("all-MiniLM-L6-v2")
vectors = model.encode(["Your text goes here"])
b. Write-time embedding
Embed text when inserted via your application.
Ensures embeddings are available immediately.
Good for chat apps, support tickets, and notes.
c. Query-time embedding
Used for user search input only.
Transforms search terms into vectors (not stored).
Passed into queries like:
ORDER BY L2_DISTANCE(embedding, '[query_vector]') ASC
3. Hybrid Search: Combine Text and Semantics
Most real-world search stacks benefit from combining keyword and vector search. MyVector enables this inside a single query:
SELECT id, title
FROM documents
WHERE MATCH(title, body) AGAINST('project deadline')
  AND user_id = 42
ORDER BY L2_DISTANCE(embedding, EMBED('deadline next week')) ASC
LIMIT 5;
This lets you:
Narrow results using lexical filters
Re-rank them semantically
All in MySQL — no sync to external vector DBs
This hybrid model is ideal for support systems, chatbots, documentation search, and QA systems.
4. Brute-Force vs. HNSW Indexing in MyVector
When it comes to similarity search, how you search impacts how fast you scale.
Brute-force search
Compares the query against every row
Guarantees exact results (100% recall)
Simple but slow for >10K rows
SELECT id
FROM documents
ORDER BY COSINE_DISTANCE(embedding, '[query_vector]') ASC
LIMIT 5;
HNSW: Hierarchical Navigable Small World
Graph-based ANN algorithm used by MyVector
Fast and memory-efficient
High recall (~90–99%) with tunable parameters (ef_search, M)
CREATE INDEX idx_vec ON documents(embedding) VECTOR
  COMMENT='{"HNSW_M": 32, "HNSW_EF_CONSTRUCTION": 200}';
Comparison
Feature
Brute Force
HNSW (MyVector)
Recall
✅ 100%
🔁 ~90–99%
Latency (1M rows)
❌ 100–800ms+
✅ ~5–20ms
Indexing
❌ None
✅ Required
Filtering Support
✅ Yes
✅ Yes
Ideal Use Case
Small datasets
Production search
5. Scoped Search as a Security Boundary
Because MyVector supports native SQL filtering, you can enforce access boundaries without separate vector security layers.
Patterns:
WHERE user_id = ? → personal search
WHERE org_id = ? → tenant isolation
Use views or stored procedures to enforce access policies
You don’t need to bolt access control onto your search engine — MySQL already knows your users.
6. HNSW Tuning for Performance
MyVector lets you tune index behavior at build or runtime:
Param
Purpose
Effect
M
Graph connectivity
Higher = more accuracy + RAM
ef_search
Traversal breadth during queries
Higher = better recall, more latency
ef_construction
Index quality at build time
Affects accuracy and build cost
Example:
ALTER INDEX idx_vec SET HNSW_M = 32, HNSW_EF_SEARCH = 100;
You can also control ef_search per session or per query soon (planned feature).
TL;DR: Production Patterns with MyVector
Use VECTOR(n) columns and HNSW indexing for fast ANN search
Embed externally using HuggingFace, OpenAI, Cohere, etc.
Combine text filtering + vector ranking for hybrid search
Use SQL filtering to scope vector search for performance and privacy
Tune ef_search and M to control latency vs. accuracy
Coming Up in Part 3
In Part 3, we’ll explore real-world implementations:
Semantic search
Real-time document recall
Chat message memory + re-ranking
Integrating MyVector into RAG and AI workflows
We’ll also show query plans and explain fallbacks when HNSW is disabled or brute-force is needed.
Semantic Search with SQL Simplicity and Operational Control
Introduction
Vector search is redefining how we work with unstructured and semantic data. Until recently, integrating it into traditional relational databases like MySQL required external services, extra infrastructure, or awkward workarounds. That changes with the MyVector plugin — a native vector indexing and search extension purpose-built for MySQL.
Whether you’re enhancing search for user-generated content, improving recommendation systems, or building AI-driven assistants, MyVector makes it possible to store, index, and search vector embeddings directly inside MySQL — with full support for SQL syntax, indexing, and filtering.
What Is MyVector?
The MyVector plugin adds native support for vector data types and approximate nearest neighbor (ANN) indexes in MySQL. It allows you to:
Define VECTOR(n) columns to store dense embeddings (e.g., 384-dim from BERT)
Index them using INDEX(column) VECTOR, which builds an HNSW-based structure
Run fast semantic queries using distance functions like L2_DISTANCE, COSINE_DISTANCE, and INNER_PRODUCT
Use full SQL syntax to filter, join, and paginate vector results alongside traditional columns
By leveraging HNSW, MyVector delivers millisecond-level ANN queries even with millions of rows — all from within MySQL.
Most importantly, it integrates directly into your existing MySQL setup—there is no new stack, no sync jobs, and no third-party dependencies.
Scoped Vector Search: The Real-World Requirement
In most production applications, you rarely want to search across all data. You need to scope vector comparisons to a subset — a single user’s data, a tenant’s records, or a relevant tag.
MyVector makes this easy by combining vector operations with standard SQL filters.
Under the Hood: HNSW and Query Performance
MyVector uses the HNSW algorithm for vector indexing. HNSW constructs a multi-layered proximity graph that enables extremely fast approximate nearest neighbor search with high recall. Key properties:
Logarithmic traversal through layers reduces search time
Dynamic index support: you can insert/update/delete vectors and reindex as needed
Configurable parameters like M and ef_search allow tuning for performance vs. accuracy
Under the Hood: HNSW and Query Performance
MyVector uses the HNSW algorithm for vector indexing. HNSW constructs a multi-layered proximity graph that enables extremely fast approximate nearest neighbor search with high recall. Key properties:
Fast ANN queries without external services
Scoped filtering before vector comparison
Logarithmic traversal through layers reduces search time
Dynamic index support: you can insert/update/delete vectors and reindex as needed
Configurable parameters like M and ef_search allow tuning for performance vs. accuracy
What’s Next
This post introduces the foundational concept of scoped vector search using MyVector and HNSW. In Part II, we’ll walk through practical schema design patterns, embedding workflows, and hybrid search strategies that combine traditional full-text matching with deep semantic understanding — using nothing but SQL.
I’m incredibly honored to share some exciting news—I’ve been recognized as an Oracle ACE Pro by Oracle!
This recognition is deeply meaningful to me, not just as a personal milestone but as a reflection of the ongoing work I’ve poured into the database community for over three decades. It’s also a reminder of how powerful open collaboration, curiosity, and mentorship can be in shaping both a career and a community.
What Is the Oracle ACE Program?
For those unfamiliar, the Oracle ACE Program recognizes individuals who are not only technically skilled but also passionate about sharing their knowledge with the wider community. It celebrates those who contribute through blogging, speaking, writing, mentoring, and engaging in forums or user groups.
The program has multiple tiers: ACE Associate, Oracle ACE, ACE Pro, and ACE Director. Each level reflects a growing commitment to community contribution and leadership. Being named an Oracle ACE Pro places me among a diverse, global group of technologists who are actively shaping the future of Oracle technologies—and open-source ecosystems alongside them.
From MySQL to ACE: A Journey Rooted in Community
My journey with data began over three decades ago, and it’s taken me across continents, companies, and countless events. My early days were steeped in MySQL—performance tuning, operations, scaling architectures—and I quickly discovered that the greatest impact didn’t come from just solving problems, but from sharing the solutions.
Since then, my path has included global roles in consulting, support, and engineering leadership. I’ve had the opportunity to speak at international conferences, publish books like the MySQL Cookbook (4th Edition), and contribute to countless community efforts in the MySQL and opensource database ecosystems.
Recognition such as Most Influential in the Database Community (Redgate 100) and MySQL Rockstar have meant a lot—but being named an Oracle ACE Pro is especially meaningful. It represents a bridge between the worlds of open source and enterprise and affirms that collaboration across ecosystems is not only possible—it’s essential.
What This Recognition Means to Me
This isn’t just about a title or a badge. To me, becoming an Oracle ACE Pro is about continuing the mission—to share what I’ve learned, amplify others doing amazing work, and give back to the communities that have shaped my path.
I’ve always believed that technical excellence must go hand in hand with generosity. Whether it’s mentoring a young DBA, helping a team scale their architecture, or writing about real-world database design challenges, the point has never been visibility—it’s always been about value.
And that’s what this recognition reflects: not just what I’ve done, but what I hope to keep doing for the next generation of data professionals.
Looking Ahead
This milestone energizes me even more to keep contributing—not just within the Oracle ecosystem but across the open-source database space. I’ll continue speaking at events, writing, mentoring, and building resources that help engineers build better, faster, and more resilient systems.
I’m also excited about promoting hybrid data architectures combining MySQL, opensource, and cloud-native technologies. This is where the industry is heading, and I’m committed to helping folks navigate that evolving landscape with clarity and confidence.
Gratitude and Community
I want to thank Oracle for running a program that not only recognizes technical contributions, but also community-driven spirit. And a heartfelt thank you to the MySQL community, open-source contributors, and peers I’ve had the privilege of working alongside over the years.
You’ve all helped shape my thinking, my work, and my growth. I stand on the shoulders of a global community, and this milestone belongs to all of us.
Let’s Stay Connected
If you’re building something, learning something, or just curious about databases, I’d love to hear from you. Whether it’s MySQL performance, opensource design, or data architecture strategy, reach out. Let’s keep learning, building, and sharing—together.
And if you’re interested in becoming part of the Oracle ACE community, feel free to ping me. I’m always happy to share what I’ve learned and help others navigate that journey.
A Note About What’s Coming
As part of my role and responsibilities as an Oracle ACE Pro, I’ll be launching a new series of technical blog posts in the coming months. These will explore cutting-edge topics including:
• AI/ML and LLMs (Large Language Models)
• Vector Search and database integration
• Real-world use cases at the intersection of AI and relational databases
These areas are rapidly evolving, and I’m excited to share practical, hands-on insights on how they tie into modern data architecture—especially within the Oracle and open-source ecosystems.
Disclaimer: The views and opinions I’ll be sharing in upcoming posts are my own and do not necessarily reflect those of Oracle or any other organization. Content will be independent, community-driven, and based on real-world experience.
Stay tuned—and if you have specific questions or topics you’d like to see covered, feel free to reach out!
Thanks for reading—and here’s to the next chapter in our database story.
In this edition of the blog post, I want to summarize my three decades (excluding my internships) of hustle in Information Technology. This is not only a tribute to my 30th anniversary in the field but also a show of appreciation for those with whom I’ve crossed paths—sharing knowledge, experiences, and moments of blood, sweat, and tears. Through this journey, I have worked to become a humble, smart, and resourceful person. I will continue to mentor and coach, share what I’ve learned, and help others achieve even greater success.
The majority of my background has been as a Database Administrator (DBA), although my academic foundation was in Electronics in high school and Software Development in college. As my career progressed, I naturally gravitated toward data management, making databases my core focus.
From the early days of navigating the evolving landscape of databases and technology to leading global teams and contributing to the open-source community, every challenge and milestone has shaped me. Along the way, I’ve had the privilege of working with brilliant minds, tackling complex problems, and building solutions that have left a lasting impact.
Of course, the databases I’ve worked with have also connected me with their respective communities. In the early days, enterprise communities were tightly controlled—corporations dictated what could and couldn’t be shared. A decade ago, we started seeing individuals clarify that their views on social media were their own and not their employer’s. Back then, when working on a project, we operated in silence—no open discussions, no forums, just internal tickets to the database provider if an issue arose. I also predate the internet, social media, and the niche forums we have today, which has given me a unique perspective on how knowledge sharing has evolved.
My journey began as a Technical Support Engineer for Informix (acquired by IBM in 2000). From there, I transitioned into full-time DBA roles across various companies—both as a consultant and a full-time employee. There are too many to list, but the key takeaway is that technology forces adaptation. As Informix declined in popularity, I shifted to Oracle and SQL Server, which dominated most of my career until I transitioned to full-scale MySQL administration. That’s where real community engagement started (link).
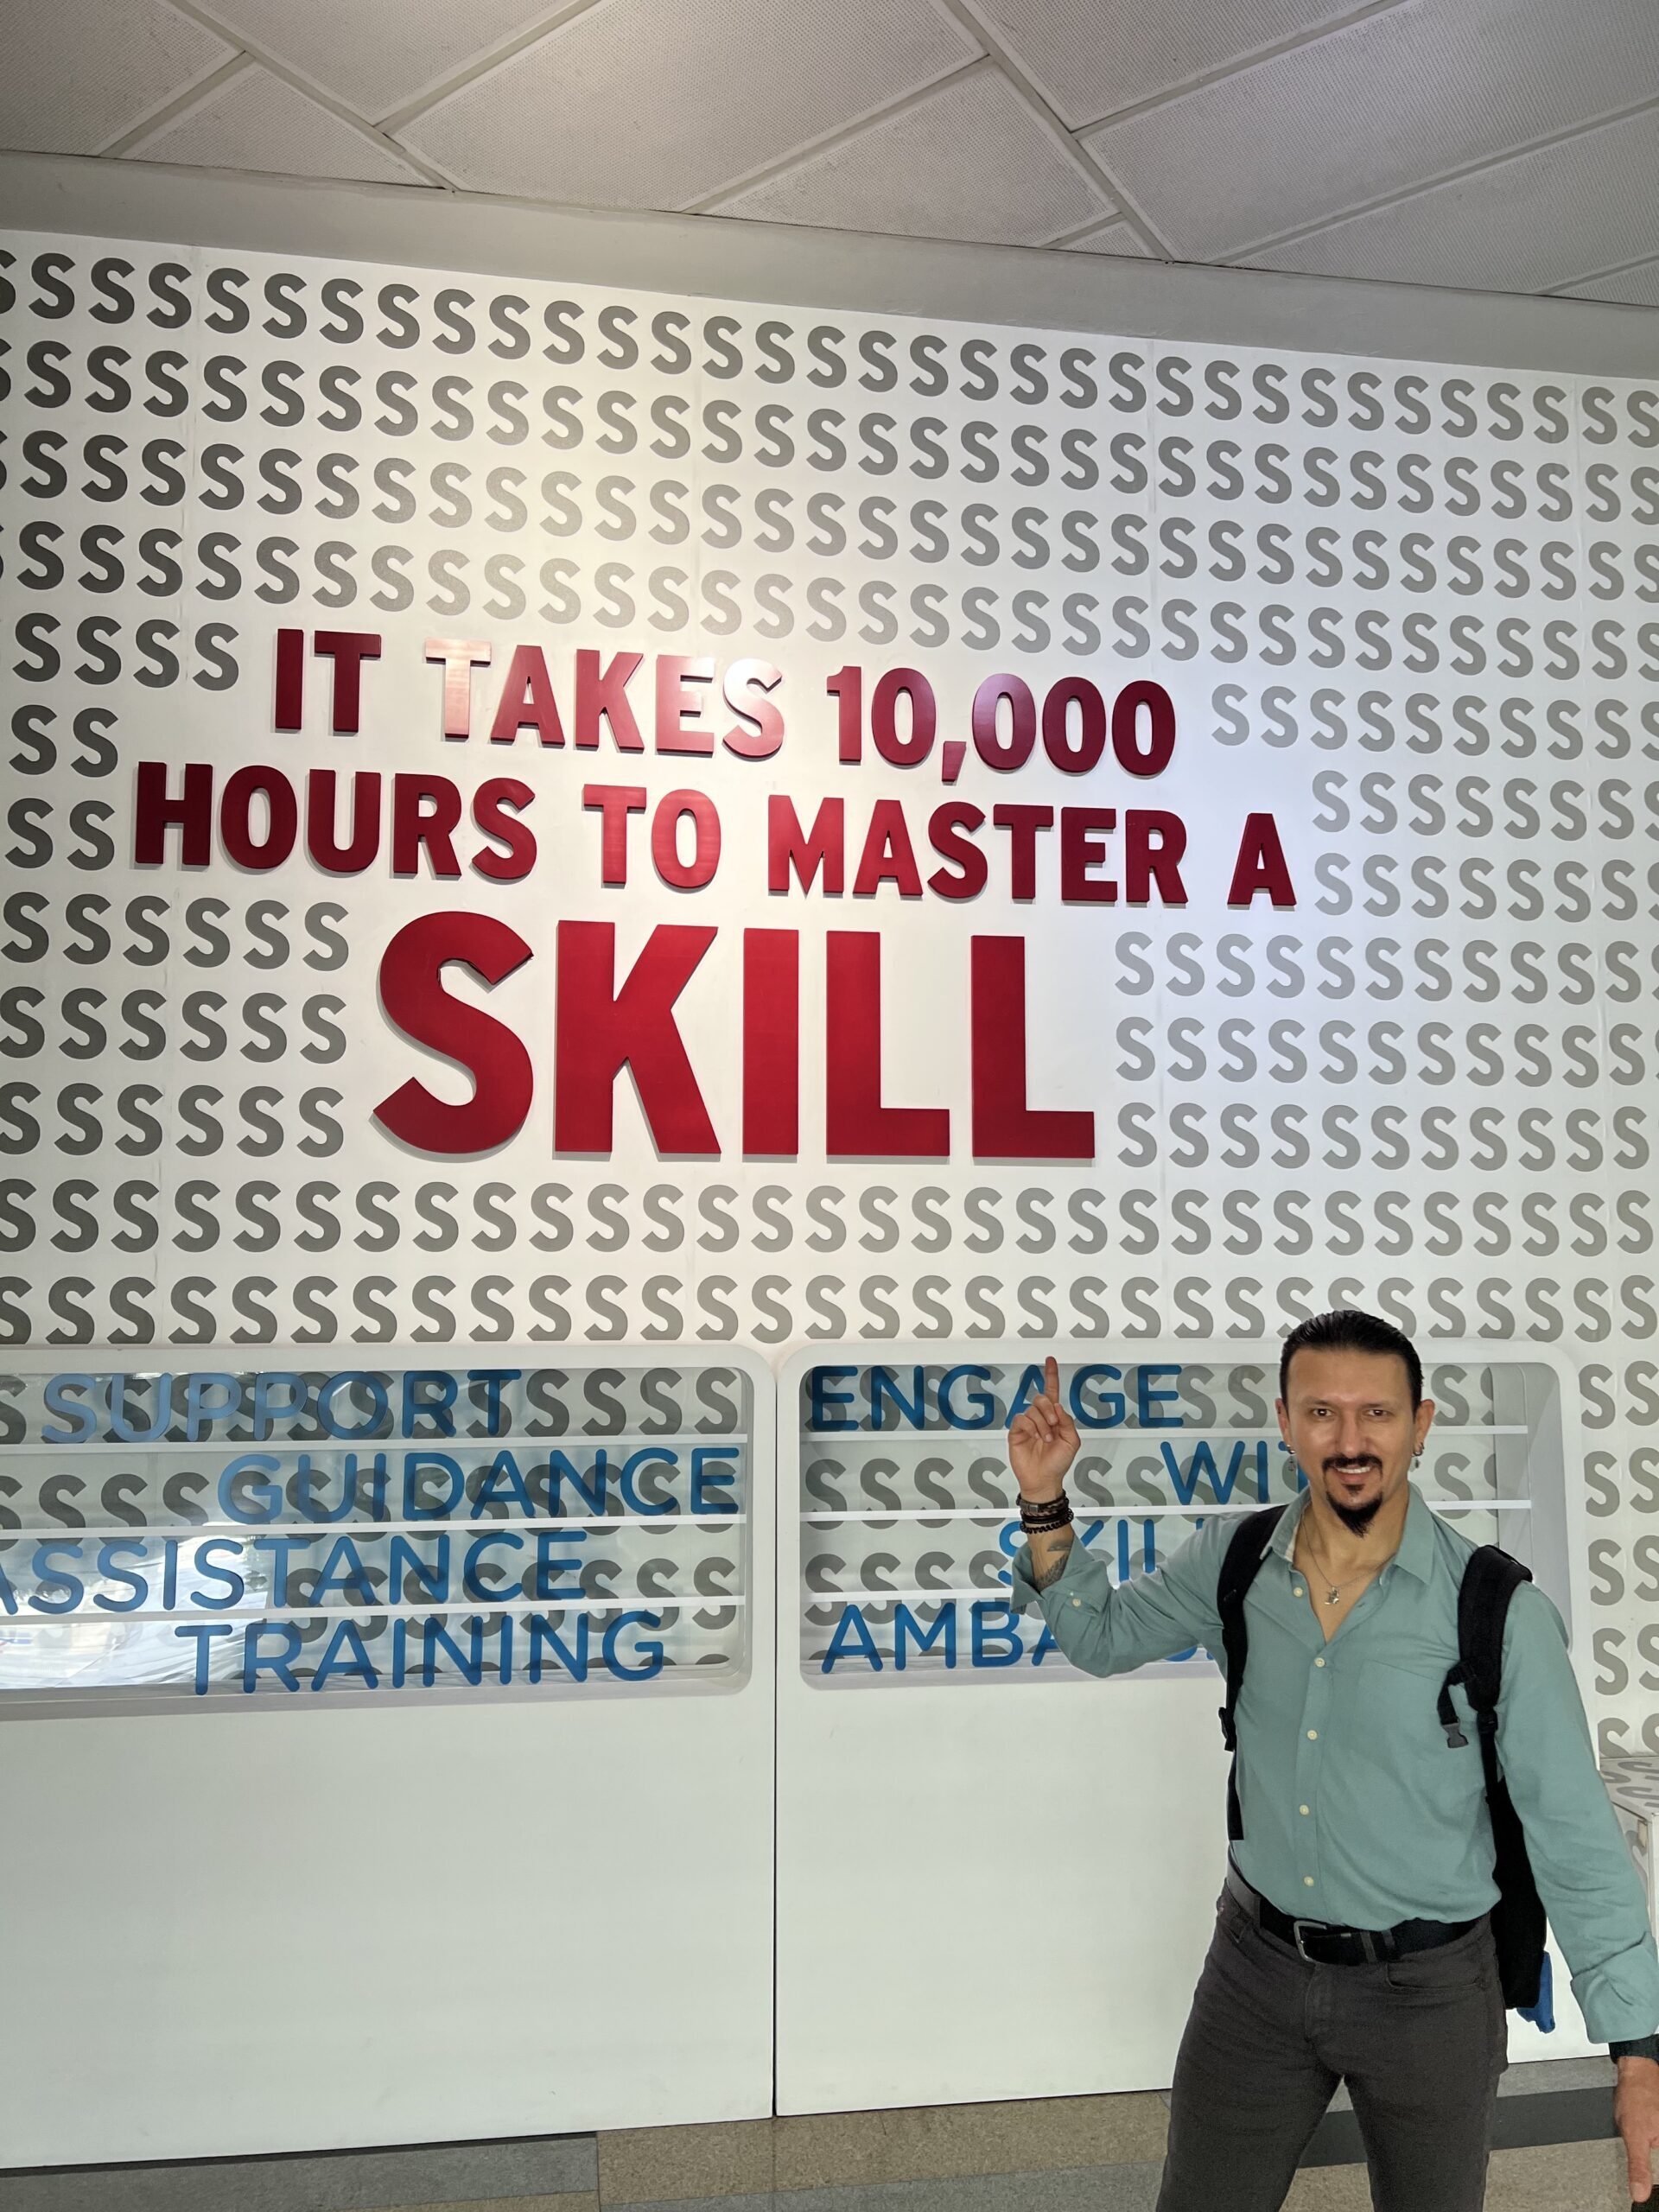
Does It Take 10,000 Hours to Master a Skill?
It does—or at least that much time to fully digest the internals of what you’re working on. Whether it’s 10,000 hours, nautical miles, or kilometers, the exact metric doesn’t matter. What does matter is the time spent developing tribal knowledge—understanding shortfalls, known issues, edge cases, strengths, and weaknesses.
Along the way, we all make mistakes. We think we’ve learned our lessons, but the reality is that learning never stops. The most important lesson I’ve learned? Never give up. The moment you step back and quit, you risk an epic failure—one that may come at a cost you can’t afford. Persistence is everything.
As I mark this 30-year milestone, I remain committed to the tech community—mentoring, coaching, and pushing the boundaries of what’s possible with open-source databases. Here’s to the next chapter and many more years of learning, teaching, and growing together.
Databases are the backbone of every data-driven application, a crucial element that fuels everything from simple web apps to complex enterprise systems. For over three decades, I have navigated the tumultuous waters of database administration, balancing technical intricacies with the often challenging dynamics of workplaces. My journey is not just one of keeping systems running but one of constant evolution—both in my career and in the technology I’ve used to build efficient and scalable databases.
The Early Days: Setting Sail
When I began my journey into database administration, the landscape was vastly different. Relational databases were becoming the cornerstone of digital infrastructure, but the tools and techniques we take for granted today were still in their infancy. Back then, designing a database was more about intuition and experience than adhering to well-defined best practices. It was like sailing uncharted waters, where the guiding stars were trial and error, persistence, and a touch of creativity.
MySQL and PostgreSQL were just emerging, promising a future of open-source solutions that could rival proprietary giants. I knew that these open-source databases were not just cost-effective alternatives but had the potential to evolve into robust, scalable solutions that could meet the demands of modern applications. I’ve had the privilege of working alongside both these databases from their early stages to their current iterations, witnessing firsthand how they’ve transformed the way we think about database design and management.
Navigating Database Design and Modeling: A Mastery in MySQL and PostgreSQL
As I worked through project after project, one lesson became crystal clear: the design and modeling of your database can make or break your entire system. Poorly designed databases lead to inefficiencies, performance bottlenecks, and often costly rework down the road. It’s akin to building a ship with weak foundations—you might stay afloat for a while, but you’re doomed when the first storm hits.
In my recent book, Database Design and Modeling with PostgreSQL and MySQL, I aim to guide readers through mastering the art of database design. This mastery goes beyond just creating tables and writing queries. It requires understanding the advanced concepts that keep systems running smoothly even when data size and complexity increase.
Normalization, for instance, often becomes essential for performance optimization. Indexing strategies are not just about speeding up queries but also managing trade-offs between read and write performance. Transaction management and concurrency control play critical roles in multi-user environments, ensuring data remains consistent even as users interact with the system simultaneously.
Scaling Databases: Preparing for the Storms Ahead
As data grows, scalability becomes a focal point. It’s one thing to manage a few gigabytes of data with ease; it’s quite another to manage terabytes or even petabytes of data without sacrificing performance. This is where techniques like sharding, replication, and load balancing come into play. They allow us to distribute workloads across multiple servers, ensuring that no single point of failure can bring down an entire system.
But scalability isn’t just about keeping your system running. It’s about preparing for the inevitable growth of your data and ensuring your database infrastructure can handle the storm.
Backup and recovery strategies are equally important. They act as your lifeboat when things go wrong—and things will go wrong in the world of databases. Without a solid recovery plan, you risk losing not only your data but also the trust of your users and stakeholders.
Integrating Databases with Modern Applications: Staying the Course
Databases don’t exist in isolation. They are integral parts of larger ecosystems connected to web and mobile applications that demand real-time, reliable data. Understanding how to connect, query, and secure your database in a modern web application environment is critical. With APIs and data layers becoming more complex, ensuring that your databases remain efficient and secure while supporting growing application demands is more important than ever.
The Future of Databases: New Horizons
While relational databases like MySQL and PostgreSQL remain essential, the database world is rapidly evolving. NoSQL databases have emerged as a popular solution for handling unstructured data, while cloud databases offer scalability and flexibility that on-premise solutions often can’t match. Integrating AI and machine learning into database systems is another frontier, opening up possibilities for smarter data management, predictive analytics, and automated optimization.
Staying ahead of these trends will be key to mastering database design and management in the years ahead. The ability to adapt to new technologies while maintaining a firm grasp on the foundational principles of database design will set the next generation of database administrators apart.
Final Thoughts: A Journey Worth Taking
Three decades in, I can say with certainty that database administration is not just a technical discipline—it’s an art. Like sailing through rough seas, it requires both skill and intuition. You must be prepared for the unexpected, adapt to changing conditions, and always keep an eye on the horizon.
Through my experiences, I’ve learned that the most successful database administrators are not those who avoid challenges but those who embrace them, using each storm as an opportunity to improve. And as we move into the future of databases, these lessons will only become more valuable. Whether you’re just starting your journey or are already deep into your career, there’s always more to learn, more challenges to face, and more opportunities to build something truly remarkable.
In Database Design and Modeling with PostgreSQL and MySQL, I aim to share these lessons and provide the tools you need to navigate your database challenges. Because at the heart of every successful system is a well-designed database—and the expertise to keep it running smoothly, no matter how rough the seas get.
I’m thankful to my co-author Ibrar Ahmed, a true professional and PostgreSQL expert. I would like to thank our publisher, Packt, for making this book possible and our primary editor, Tiksha Lad, product manager, Apeksha Shetty, and project manager,Aparna Nair , and the rest of the Packt staff. I also would like to send my gratitude to our technical reviewers Frederic Descamps , Naresh Miryala, and Seemanjay Ameriya. Not to forget our foreword author, Peter Zaitsev; we are grateful for his valuable time.
After the most memorable MySQL community event, #MySQLBelgianDays2024, and earning legendary recognition from the MySQL Community team, I have decided to share some thoughts about the importance of a community.
Previously in life
As a former enterprise DBA, I have been part of other communities strictly focused on monetary and entitlement of accomplishments. I had a chance to work on world-leading enterprises and had ability access to the most advanced technologies for both software and hardware. This journey was fun, fruitful, and rewarding for me.
In the latter half of my career, I entered the open-source community of MySQL by shifting my prior decade and a half of experience into it.
Entry to the open-source community
When I entered this community full-time, there were several controversial discussions and assumptions about Oracle’s acquisition of MySQL, the separation of MariaDB, etc. While some of those claims had some reality, most turned out to be baseless without knowing the intentions and future.
The importance of Percona Live events and the Oracle MySQL team’s contributions to this community, which several other open-source contributors surrounded, was my entry point. There was a significant influence from hyper-scalers, known as initially social media companies, followed by SAAS and cloud vendors.
I have watched, followed, and strictly learned from community leaders, including influencers like Peter Zaitsev. Although open-source communities feel and look like closed-circuit groups of geeks having fun, they are very open to newcomers. But remember, communities accept contributors, not watchers. What I mean by contributors is not just coming to a company-paid trip to the event once in a blue moon. Even if you attend an event as a visitor, you can still help by promoting and getting the word out through social media and other networks.
Where to start?
One can share ideas, code tools, and software and become a speaker. If you aren’t the type of person who can speak and present, you can help others by providing content and ideas and having them review them. Let me help you get there and recognitions will follow.
How do I start helping and becoming a part of the community?
Create a public repository of the tools and code you spend time on.
Start writing blogs about your experiences and sharing content.
Become a speaker or co-speaker with the same or similar subject.
Conduct webinars and post-speaking events for those who were not able to attend. Include feedback and corrections to your talk.
Create training content on recorded videos and training sites.
Coordinate or help with local meetups.
Help sponsoring events.
Encourage to send co-workers to events.
Introduce newcomers to community veterans.
Author or co-author books and booklets.
Act as an event committee member.
Help to answer questions via GitHub issues or Slack channels.
Always spread the word through social channels.
If you still can’t do any of those, help marketing colleagues carry boxes of swag and give away materials, and set up and clean up booths for the events. You can always help sales and pre-sales folks by connecting your network.
I have to credit Laine Campbell for introducing me to and allowing me to meet the most influential leaders of the MySQL community.
Many thanks to Peter Zaitsev for all the help, support, and openness in accepting me into the MySQL community.
I would also like to thank the past, current, and future MySQL Community team for their hard work. The rest of the list is too long to mention here, but they know who they are.
Congratulations to all previous MySQL Rockstars and 2023 winners.
Alkin Tezuysal was named Most Influential in the Database Community 2022 by The Redgate 100 — an annual ranking by Redgate Software spotlighting the database community’s most impactful contributors. Alkin was recognized in the Open Source Database category.
The recognition reflects his 30+ years working across open-source relational databases, his leadership of global MySQL operations teams, his conference speaking, and his work bridging enterprise adoption with open-source communities.